| Myth | Reality |
|---|---|
| “Anonymised” data in a vendor contract means it is legally anonymous. | Vendors routinely use “anonymised” as marketing language for what regulators would classify as pseudonymised, or worse, weakly de-identified data still carrying re-identification risk. |
| Removing names and emails is enough to anonymise a dataset. | Direct identifiers are only part of the picture; quasi-identifiers like ZIP code, birth date, and gender can re-identify most people when combined, as repeated academic studies have shown. |
| Pseudonymised data is basically safe because the key is stored elsewhere. | Under GDPR, pseudonymised data is still personal data in the hands of anyone who can plausibly obtain the key, including through legal process or a breach of the separate system. |
| Once you anonymise data, you can do whatever you want with it forever. | Anonymisation is a point-in-time claim; new datasets, new linkage techniques, or new auxiliary information can undo it later, so the claim needs periodic re-testing. |
Why This Distinction Keeps Tripping Up Otherwise Careful Teams
Every privacy program eventually runs into the same sentence in a vendor’s data processing agreement: “the data is anonymised, so GDPR does not apply.” That sentence is doing an enormous amount of legal work, and it is wrong more often than it is right. The difference between anonymisation and pseudonymisation is not a matter of degree — it is a binary legal boundary. On one side of that boundary, a regulator has no jurisdiction because there is, in principle, no identifiable person left in the data. On the other side, every obligation in the GDPR, the UK GDPR, and comparable frameworks like Brazil’s LGPD or California’s CCPA/CPRA still applies in full.
Recital 26 of the GDPR is explicit about this: the regulation “does not therefore concern the processing of such anonymous information, including for statistical or research purposes.” But the same recital sets a demanding bar — data counts as anonymous only when the data subject is not or no longer identifiable, taking into account “all the means reasonably likely to be used” by the controller or any other person. That last clause is the trap. It does not ask whether you personally can re-identify someone; it asks whether anyone reasonably could, given auxiliary datasets that exist in the world right now.
Anonymisation: The Legal Promise of No Way Back
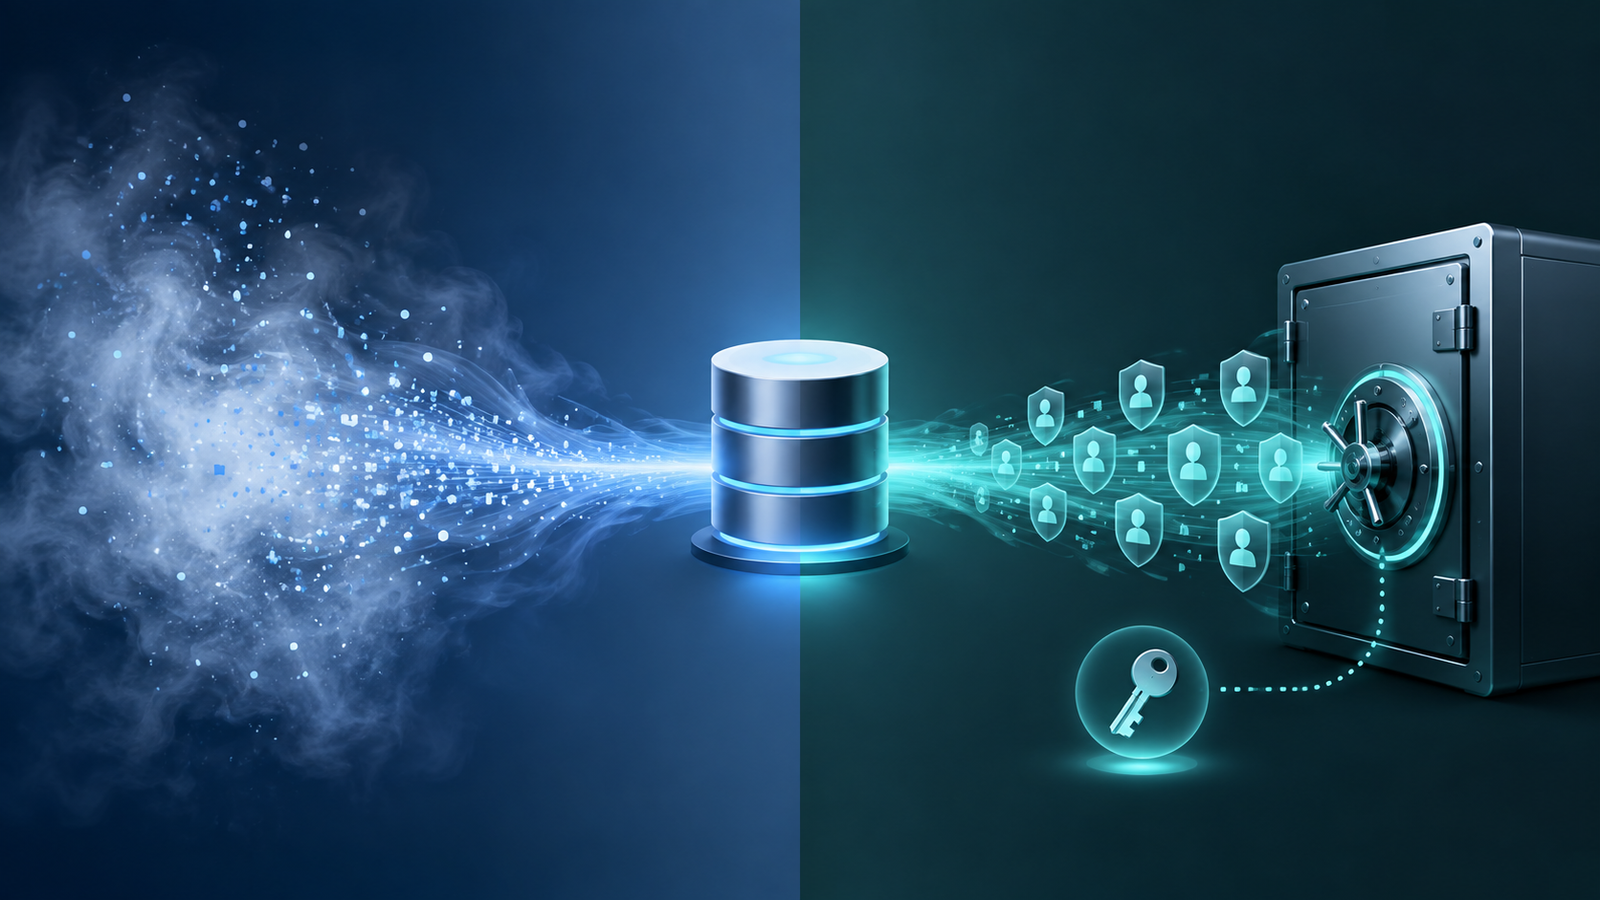
Anonymisation is supposed to be irreversible. The technique removes or transforms data so thoroughly that no reasonably available method could reconstruct an individual’s identity, even by combining it with other datasets. Common anonymisation techniques include:
- Aggregation: reporting only group-level statistics (e.g., average transaction value per region) rather than any row-level record.
- Generalisation: replacing precise values with ranges, such as converting an exact age into a ten-year bracket.
- Noise addition (differential privacy): injecting calibrated statistical noise into query results so no single record materially changes the output.
- k-anonymity, l-diversity, and t-closeness: formal models that ensure each record is indistinguishable from at least k-1 others across quasi-identifiers, with extensions to guard against attribute disclosure.
- Permanent deletion of the key: if a pseudonym was ever used, anonymisation requires destroying the mapping table entirely, not just restricting access to it.
Genuinely anonymised data falls outside the scope of GDPR, UK GDPR, and most comparable regimes. That is a powerful incentive: it means the data can be shared more freely, retained indefinitely, and used for secondary purposes without the consent and purpose-limitation constraints that apply to personal data. It is also exactly why organisations are tempted to claim anonymisation when they have only achieved something weaker.
Pseudonymisation: Regulated, Reversible, and Still Personal Data
Pseudonymisation, as defined in GDPR Article 4(5), means processing personal data so that it can no longer be attributed to a specific person without additional information — provided that additional information is kept separately and subject to technical and organisational measures ensuring non-attribution. The key word is “without additional information”: the additional information exists, and someone holds it. That is what makes pseudonymisation reversible in principle, even if access to the key is tightly controlled.
Because the data can theoretically be re-linked to a person, GDPR explicitly continues to classify pseudonymised data as personal data (Recital 26 again: “Personal data which have undergone pseudonymisation… should be considered to be information on an identifiable natural person”). What pseudonymisation buys you is not exemption from the law — it is recognition as a security and data-protection-by-design measure. Article 25 lists pseudonymisation as an example of an appropriate technical measure, and Article 32 lists it as an example of a security control appropriate to risk. Regulators and courts also treat robust pseudonymisation as a mitigating factor when assessing breach severity and administrative fines.
| Attribute | Anonymisation | Pseudonymisation |
|---|---|---|
| Reversibility | Intended to be irreversible | Reversible with the separately held key |
| Regulatory status | Outside GDPR-style personal data scope | Still personal data, fully in scope |
| Consent/purpose limitation | Not required post-anonymisation | Still required |
| Breach notification duty | Not triggered (no personal data involved) | Still triggered if key and data are both exposed |
| Typical use case | Public statistics, open datasets, long-term research archives | Internal analytics, clinical trials, fraud models, testing environments |
| Re-identification risk | Should be negligible if done correctly, but rarely zero | Explicit and accepted, mitigated by key segregation |
The Re-identification Research That Undermines “Anonymised” Claims
The uncomfortable finding from over a decade of academic work is that most datasets marketed as “anonymised” are not, in the strict legal sense. Latanya Sweeney’s foundational 2000 study showed that 87 percent of the U.S. population could be uniquely identified using just three attributes: five-digit ZIP code, birth date, and gender. That result alone should have ended the practice of treating quasi-identifier removal as sufficient, but the pattern has repeated at larger scale since.
A 2019 Nature Communications paper by Rocher, Hendrickx, and de Montjoye, “Estimating the success of re-identifications in incomplete datasets using generative models,” built a statistical model that correctly re-identified 99.98 percent of Americans in any dataset using just 15 demographic attributes — even when the dataset was a small, incomplete sample rather than a full population census. That figure matters because a common defence of “anonymised” releases is that they only include a subset of the population; the Rocher study specifically demonstrates that incompleteness does not meaningfully protect against re-identification once enough auxiliary attributes are available.
How re-identification actually happens
An attacker rarely needs a name field. A “de-identified” hospital discharge record with ZIP code, birth date, and sex can be cross-referenced against a public voter roll containing the same three fields alongside real names — the intersection uniquely identifies most individuals. This is the same mosaic effect that lets analysts re-link “anonymised” location, purchase, or browsing datasets to real people once a second dataset with overlapping quasi-identifiers becomes available, whether through a data broker, a leak, or a public records request.
The mosaic effect is the reason regulators evaluate anonymisation claims against “all the means reasonably likely to be used,” not just the means available to the controller today. A dataset that looks safely anonymous in isolation can become re-identifiable the moment a new, unrelated dataset enters the public domain — something the controller does not control and often cannot foresee. This is also why data protection authorities, including the UK’s ICO and France’s CNIL, have both published anonymisation guidance stressing that anonymisation is a risk-based, ongoing assessment rather than a one-time technical checklist.
A Practical Decision Framework
When a team has to decide which approach fits a given dataset, the following sequence of questions is more useful than the marketing labels on a vendor datasheet.
- Does anyone, anywhere, retain a way to reverse this transformation? If a key, salt, lookup table, or even a documented algorithm with a known seed exists and is retained by any party, you have pseudonymisation, not anonymisation, regardless of what the data is called internally.
- What auxiliary data could plausibly exist? Voter rolls, social media profiles, data broker files, and breach dumps are all “reasonably likely” auxiliary sources under current regulatory guidance. If your quasi-identifiers overlap meaningfully with any of these, treat the dataset as re-identifiable.
- What is the k-anonymity level, honestly measured? If any combination of retained attributes narrows a group down to fewer than roughly 10-20 people (guidance varies by regulator and sensitivity), the dataset likely fails a reasonable anonymisation test.
- Who benefits from getting the classification wrong? If a “anonymisation” claim conveniently removes a dataset from consent requirements, retention limits, or subject access rights, that is a signal to apply extra scrutiny, not less.
- Can the claim survive re-testing in 12 months? Anonymisation should be revisited whenever the threat landscape changes — new datasets are published, new linkage techniques are demonstrated, or the dataset itself is combined with something new internally.
| Technique | Category | Typical re-identification resistance |
|---|---|---|
| Direct identifier removal only (name, email, phone) | De-identification (weak) | Low — quasi-identifiers usually remain |
| Tokenisation with a retained mapping table | Pseudonymisation | Reversible by design; protection depends entirely on key security |
| k-anonymity with k ≥ 20 plus l-diversity | Statistical anonymisation | Moderate to strong, weakens against auxiliary linkage over time |
| Formal differential privacy with a defined privacy budget | Mathematical anonymisation | Strong and quantifiable, but reduces data utility as noise increases |
| Full aggregation with suppressed small cells | Statistical anonymisation | Strong for published statistics, unsuitable for row-level analytics |
Common mistake
Teams often treat pseudonymisation as a compliance finish line because the word sounds close to “anonymous.” In reality, calling data pseudonymised is an admission that it remains personal data — the practical benefit is a reduced breach-severity assessment and a stronger data-protection-by-design posture under Article 25, not an exemption from GDPR obligations like lawful basis, retention limits, or subject access requests. Contracts and data flow diagrams should say “pseudonymised, still regulated” rather than implying otherwise.
What worked
Organisations that hold up well under regulatory scrutiny typically pair pseudonymisation for operational and analytics data (with the re-identification key held by a separate team or entity under strict access controls) with true statistical anonymisation only for data intended for external publication or long-term open release. They also re-run a re-identification risk assessment whenever a new external dataset becomes public that shares quasi-identifiers with their own, rather than assuming a one-time anonymisation sign-off holds forever.
Where Each Approach Fits in a Real Data Program
Pseudonymisation tends to be the right tool inside the perimeter: internal analytics pipelines, machine learning training sets that will later be discarded, clinical trial data where re-identification is sometimes legitimately necessary (for example, to report an adverse event to a participant), and fraud detection systems that need to escalate a case back to a real customer. In every one of these cases, the organisation wants the option to reverse the process under controlled conditions, which is precisely what pseudonymisation preserves.
Anonymisation is the right tool when data is leaving the organisation’s control entirely, or when it will be retained indefinitely beyond any legitimate purpose limitation — open government datasets, published research corpora, long-term aggregate business intelligence dashboards shared with the public, or statistics handed to a regulator as evidence of market trends. The tradeoff is real: anonymisation techniques that are strong enough to survive scrutiny (heavy aggregation, differential privacy noise, small-cell suppression) reduce the analytical precision of the data. A team that anonymises too aggressively ends up with numbers too coarse to be useful; a team that anonymises too lightly ends up with a compliance liability disguised as a compliance win.
- Mosaic effectThe risk that combining several “safe” datasets, each individually non-identifying, produces a combination that re-identifies people — the reason anonymisation assessments must consider external data, not just the dataset in isolation.
- Quasi-identifiersAttributes like ZIP code, birth date, gender, or job title that are not identifying alone but become identifying in combination — the most commonly underestimated re-identification vector.
- Key segregationStoring the pseudonymisation mapping table in a separate system, under separate access controls, from the pseudonymised dataset itself — a control regulators specifically look for during audits.
- Re-identification risk assessmentA documented, periodically repeated evaluation of whether a dataset’s anonymisation claim still holds given current auxiliary data availability — not a one-time technical sign-off.
- Purpose limitation driftThe gradual expansion of what a pseudonymised dataset is used for beyond its originally documented purpose, often the actual trigger for a regulatory finding, independent of the technical anonymisation quality.
- Synthetic data as an alternativeStatistically modelled data generated to mimic real data’s properties without mapping to any actual individual, increasingly used where true anonymisation would strip too much analytical value.
How This Connects to Broader Data Protection Strategy
Anonymisation and pseudonymisation decisions rarely happen in isolation — they interact with retention schedules, cross-border transfer strategy, and consent architecture. A dataset that is pseudonymised for internal use in the EU, for example, still needs a valid cross-border transfer mechanism if it is processed by a vendor outside the EEA, exactly the situation addressed by the current legal mechanisms for cross-border data transfer after Schrems II. Similarly, a retention policy has to treat pseudonymised data as personal data with a defined deletion trigger, unlike genuinely anonymised statistical extracts, which is the core distinction covered in a practical guide to designing data retention policies with automated deletion.
Where an organisation operates across multiple jurisdictions, the anonymisation-versus-pseudonymisation line can shift depending on which region’s definition of “identifiable” applies, which is one of several operational realities covered in a region-by-region look at data sovereignty requirements around the world. And because differential privacy and k-anonymity are the analytical backbone of defensible anonymisation, teams building internal reporting pipelines benefit from the deeper technical treatment in a companion piece on privacy-enhancing technologies for analytics teams. Finally, none of these controls substitute for building minimisation into the data pipeline from the outset, the subject of a dedicated look at data minimisation by design in AI products, or for getting the underlying consent capture right in the first place, covered in a guide to consent management in a cookieless web.
Building an Anonymisation Governance Process
A defensible program needs more than a one-off technical choice — it needs a repeatable governance process. That typically includes a documented anonymisation or pseudonymisation decision for every dataset before it leaves its originating system, a named owner for any retained re-identification key, a periodic (at minimum annual) re-assessment of anonymisation claims against newly available auxiliary data, and a clear escalation path when a dataset that was previously classified as anonymous is found to be re-identifiable. Legal, security, and data engineering teams should sign off jointly, because the technical anonymisation method, the legal classification, and the operational access controls all have to align for the claim to hold up under scrutiny.
Documentation matters as much as the technique itself. Regulators investigating a claimed anonymisation will ask for the methodology, the k-anonymity or differential privacy parameters used, the auxiliary datasets considered during the risk assessment, and the date of the last review. Teams that can produce this paper trail are in a fundamentally different position than teams that can only say “we removed the names.”
- Anonymisation
- The process of transforming personal data so that no individual can reasonably be re-identified from it, removing the data from the scope of GDPR-style regulation.
- Pseudonymisation
- Processing personal data so it cannot be attributed to a specific person without additional, separately held information, while remaining classified as personal data.
- k-anonymity
- A formal privacy model requiring that every record in a dataset be indistinguishable from at least k-1 other records across a defined set of quasi-identifying attributes.
- Differential privacy
- A mathematical framework that adds calibrated random noise to query outputs or data releases so that the presence or absence of any single individual’s record has a bounded, quantifiable effect on the result.
- Quasi-identifier
- An attribute, such as birth date or ZIP code, that does not identify a person alone but can do so when combined with other quasi-identifiers or external data.
- Mosaic effect
- The phenomenon where combining multiple individually non-identifying datasets produces a combination capable of re-identifying individuals.
Key Takeaways
- Anonymisation is meant to be irreversible and removes data from GDPR-style regulation; pseudonymisation is reversible with a separately held key and remains regulated personal data.
- GDPR Recital 26 requires anonymisation to hold up against “all the means reasonably likely to be used” by any party, not just the controller’s own current capabilities.
- Latanya Sweeney’s classic study found 87 percent of Americans identifiable from just ZIP code, birth date, and gender; a 2019 Nature Communications study found 99.98 percent re-identifiable from 15 attributes even in incomplete datasets.
- Pseudonymisation is explicitly listed in GDPR Articles 25 and 32 as a data-protection-by-design and security measure, not as an exemption from the regulation.
- The mosaic effect means an anonymisation claim can be undone later by a new, unrelated public dataset the original controller never anticipated.
- k-anonymity, l-diversity, differential privacy, and aggregation are the main technical routes to defensible anonymisation, each trading off analytical utility for re-identification resistance.
- A defensible program documents the technique, the parameters used, the auxiliary data considered, and a review date — not just a one-time “we removed the names” claim.
FAQs
Is pseudonymised data still considered personal data under GDPR?
Yes. GDPR Recital 26 and Article 4(5) both treat pseudonymised data as personal data because it can be re-attributed to an individual using additional information kept separately. All GDPR obligations, including lawful basis, retention limits, and subject rights, continue to apply.
What makes data legally “anonymous” rather than pseudonymised?
Data is legally anonymous only when no reasonably likely means exists, for the controller or any other party, to re-identify individuals, considering available technology and auxiliary datasets. If any retained key, mapping, or plausible external linkage could reverse it, it is pseudonymised, not anonymous.
How many attributes does it typically take to re-identify someone?
Latanya Sweeney’s research found ZIP code, birth date, and gender alone identified 87 percent of Americans. A 2019 Nature Communications study found that just 15 demographic attributes correctly re-identified 99.98 percent of Americans, even in incomplete datasets.
Does removing names and email addresses count as anonymisation?
No. Removing direct identifiers alone is de-identification, a weaker step that typically leaves quasi-identifiers like location, age, and demographic details intact, which is often enough for re-identification through the mosaic effect described above.
Can anonymised data become re-identifiable later?
Yes. Anonymisation is assessed against current auxiliary data and techniques. A new public dataset, a data breach elsewhere, or a new linkage technique can retroactively undermine a previously valid anonymisation claim, which is why periodic re-assessment is recommended.
What is k-anonymity and why does it matter for anonymisation claims?
k-anonymity requires that each record be indistinguishable from at least k-1 others on quasi-identifying attributes. A higher k value means a stronger anonymisation claim, but most practical guidance treats values below roughly 10-20 as insufficient for genuinely sensitive data.
Is differential privacy the same thing as anonymisation?
Differential privacy is one rigorous, mathematically quantifiable technique for achieving anonymisation, particularly for aggregate statistics and query results. It is not automatically equivalent to legal anonymisation status, which still depends on the overall re-identification risk assessment.
Why do vendors sometimes mislabel pseudonymised data as anonymised?
The distinction reduces vendor compliance burden and contractual liability, since “anonymised” data implies no ongoing GDPR obligations. Buyers should independently verify the technique used rather than relying on the vendor’s label, since misclassification is a common and consequential error.
References
- Rocher, L., Hendrickx, J.M., de Montjoye, Y.A. “Estimating the success of re-identifications in incomplete datasets using generative models,” Nature Communications, 2019.
- Imperial College London, “Anonymising personal data ‘not enough to protect privacy,’ shows new study,” Imperial News, 2019.
- IAPP, “Looking to comply with GDPR? Here’s a primer on anonymization and pseudonymization.”
- Privacy Company Blog, “What are the Differences Between Anonymisation and Pseudonymisation.”
- arXiv, “Practical and Ready-to-Use Methodology to Assess the re-identification Risk in Anonymized Datasets,” 2025.
- European Commission, General Data Protection Regulation, Recital 26 and Articles 4(5), 25, 32.