A data contract is an explicit, enforced agreement between the team that produces a dataset and the teams that consume it, covering schema, semantics, freshness, and change management. Contracts stop upstream changes from silently breaking downstream pipelines by validating compatibility automatically, in CI and at runtime, before a breaking change ever reaches production.
| Myth | Fact |
|---|---|
| A data contract is just a schema file checked into a repository. | A contract is an enforced agreement covering schema, semantics, freshness, and change management, validated automatically, not just documentation. |
| Data contracts are only needed between separate companies. | Most breakage happens between internal producer and consumer teams inside the same organisation, which is where contracts add the most value. |
| Schema registries alone are enough to prevent downstream breakage. | A schema registry enforces structural compatibility, but a full contract also defines ownership, service level expectations, and semantic meaning that a registry does not capture. |
| Contracts slow teams down by adding approval overhead. | Well-automated contracts catch breaking changes in CI, which is faster than debugging a production incident days after a silent schema change shipped. |
| Once a contract is written, it never needs to change. | Contracts are versioned artifacts; they evolve deliberately through compatibility rules and can deprecate old versions on a defined timeline. |
Why Producers and Consumers Keep Breaking Each Other
A backend engineer renames a field, drops a column they think is unused, or changes a timestamp format, and three teams downstream find out only when their dashboards go blank or their machine learning pipeline starts failing silently. This pattern repeats at almost every company that scales past a handful of services, because the team producing an event or a table rarely has visibility into everyone consuming it.
Traditional fixes, documentation wikis, Slack messages, or a quarterly data governance meeting, do not scale because they depend on humans remembering to update humans. A data contract replaces that dependency with an enforced, machine-checkable agreement. It sits between the producer and the consumer, and it fails a build or blocks a deployment the moment a change would break the agreement, rather than letting the break ship quietly into production.
What Is a Data Contract?
A data contract is a formal, versioned specification that defines what a dataset or event stream looks like and how it is allowed to change. It is enforced through tooling rather than trust, and it typically covers four distinct areas.
Schema and Structure
The contract defines field names, types, nullability, and required versus optional fields. This is the layer most people think of first, and it is usually enforced through a schema registry such as those used with Apache Kafka topics or Protocol Buffers.
Semantic Meaning
Structure alone does not stop a producer from changing what a field means. A contract also documents business meaning, for example whether a revenue field is gross or net, and in which currency, so a structurally valid change cannot silently corrupt downstream calculations built on a domain-owned data product.
Service Level Expectations
Consumers need to know how fresh the data will be, how often it updates, and what happens if the producer’s pipeline fails. A contract states these expectations explicitly, so a consumer building a real-time feature knows not to depend on a dataset that only refreshes nightly.
Ownership and Change Process
Every contract names an accountable owner and a documented path for proposing changes, including a deprecation window before a breaking change takes effect. This turns a vague sense that “someone owns this” into an actual escalation path when something breaks.
How Data Contracts Get Enforced in Practice
A contract that lives only in a document is not really a contract; it is a suggestion. Enforcement is what separates the two, and it usually happens at three points in the data lifecycle.
Schema Registries
Tools such as Confluent Schema Registry for Kafka topics, or Buf’s schema registry for Protocol Buffers and gRPC services, store the canonical schema for a topic or service and reject producers that attempt to publish an incompatible message. This is the most mature and widely adopted enforcement mechanism available today.
CI and CD Validation
Before a producer’s code is even deployed, a pipeline step compares the proposed schema change against the registered contract and the compatibility rules attached to it, failing the build if the change would break existing consumers. This is conceptually similar to contract testing patterns used in event-driven serverless architectures, where producers and consumers are deployed independently and cannot rely on a shared release cycle to catch incompatibilities.
Runtime Monitoring
Even with registry and CI checks, some breakage only shows up in production, for example a sudden spike in null values or a distribution shift in a numeric field. Runtime monitoring watches live data against the contract’s expectations and alerts the producer and consumer teams before the anomaly propagates further downstream.
Contract Enforcement Across the Pipeline
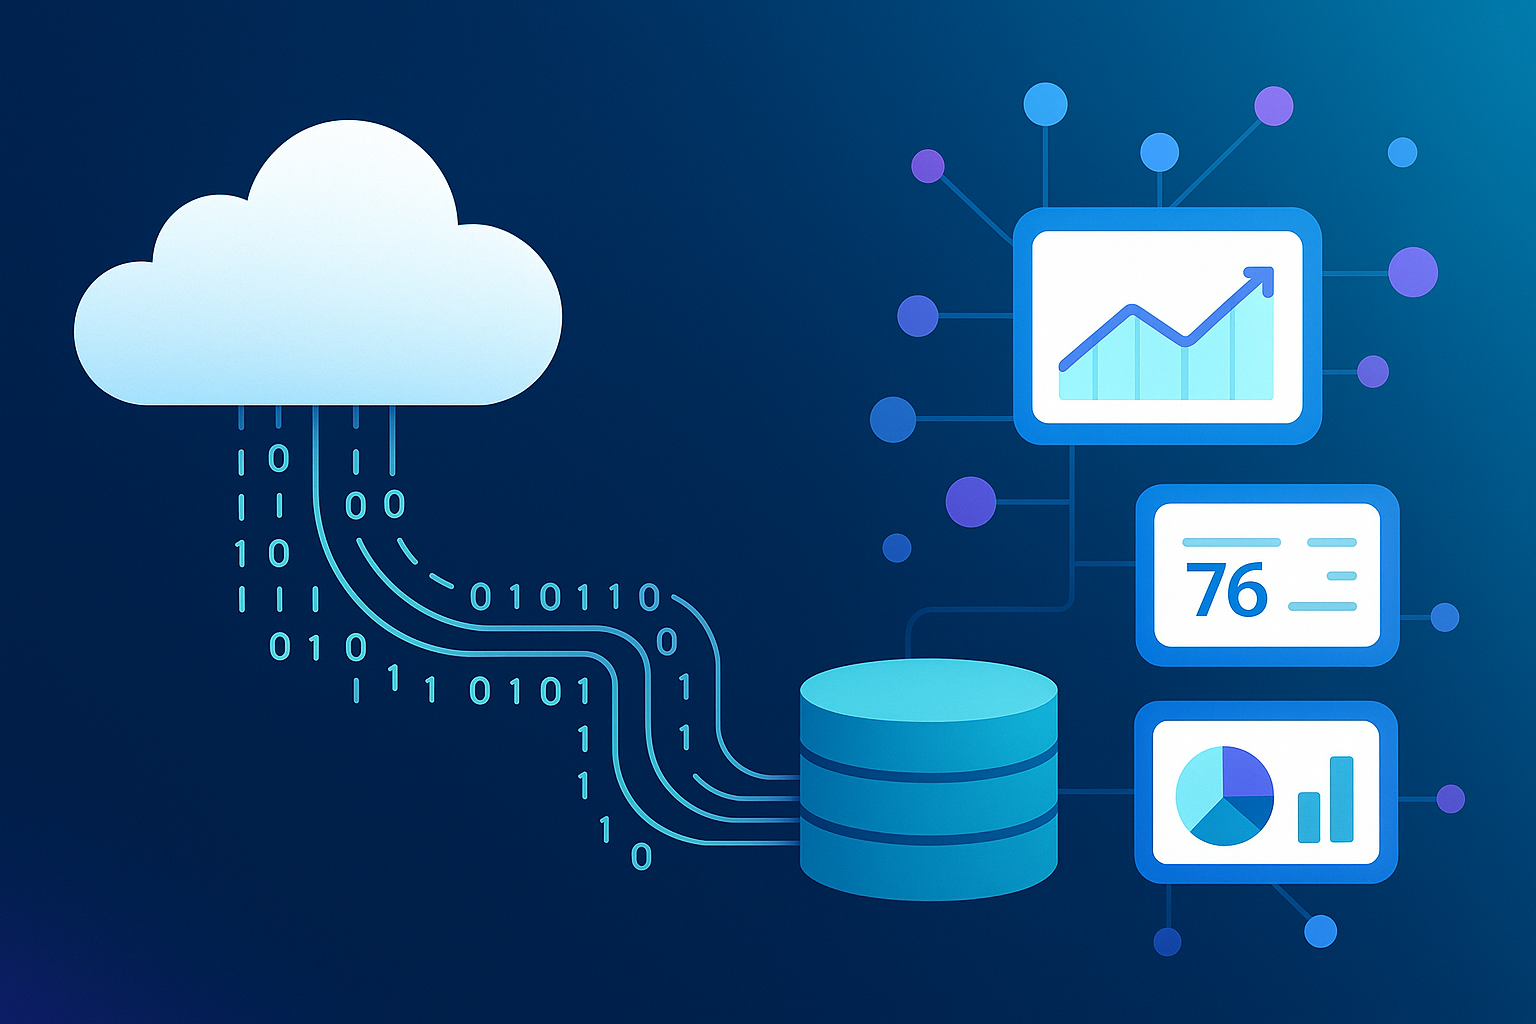
A producer’s proposed schema change is checked against the registry at build time, blocked in CI if it breaks compatibility rules, and monitored at runtime for semantic drift that structural checks alone cannot catch.
Data Contracts vs Related Concepts
Data contracts are frequently confused with adjacent practices that solve overlapping but distinct problems.
| Concept | What It Covers | What It Misses |
|---|---|---|
| Schema registry | Structural compatibility of messages or tables | Ownership, freshness expectations, and business meaning |
| Data quality tests | Statistical checks on values after data lands | Prevention before a breaking change ships |
| API contract (OpenAPI) | Request and response shape for synchronous services | Asynchronous event streams and batch datasets |
| Data contract | Schema, semantics, freshness, and ownership, enforced end to end | Nothing by design, though it depends on consistent adoption across teams |
Designing a Data Contract That Actually Holds
A contract is only as good as the compatibility rules and processes behind it. Two design choices determine whether it survives contact with a fast-moving engineering organisation.
Versioning and Compatibility Rules
Contracts should specify whether changes must be backward compatible, forward compatible, or both, and tooling should reject any change that violates the declared rule. Additive changes, such as a new optional field, are usually safe; removing or renaming a field is not, and should require a new major version.
Deprecation Windows
Breaking changes should never happen overnight. A documented deprecation window, often thirty to ninety days depending on the criticality of the downstream consumers, gives every dependent team time to migrate before the old version is retired. This same discipline matters wherever teams are wiring together event-driven internal processes, since automated workflows have no human in the loop to notice a silent break.
The Data Contract Lifecycle
A proposed change moves from draft, through automated compatibility review and a consumer notification period, into a deprecation window for the old version, before finally retiring the prior contract version.
Common Mistakes Teams Make
Mistake
Writing a contract as a static document that nobody automates against, so it silently drifts out of sync with the real schema within a few months.
Mistake
Enforcing structural compatibility through a schema registry while leaving semantic meaning undocumented, so a field stays valid but starts meaning something different.
Mistake
Skipping a deprecation window entirely and retiring an old schema version the same day a new one ships, breaking every consumer that has not yet migrated.
Mistake
Assigning contract ownership to a team rather than a named individual or role, which means nobody responds when a compatibility check fails at two in the morning.
Mistake
Treating contracts as a one-time project instead of an ongoing practice, so new datasets launched after the initial rollout never get a contract at all.
How Expert Teams Operationalize Contracts
Practice
Mature data organisations treat the contract as the interface, not the pipeline code behind it. Producers can rewrite their internal implementation freely as long as the published contract does not change, which gives engineering teams room to refactor without coordinating every internal change with downstream consumers.
Practice
Contract violations are treated as build failures, not warnings. Teams that make compatibility checks a hard gate in CI see dramatically fewer production incidents than teams that only log a warning when a check fails, because a warning is easy to ignore under deadline pressure.
Practice
Cost and reliability tracking are tied to contract violations, since a repeated pattern of breaking changes from one producer is often a signal of understaffing or unclear ownership rather than a purely technical problem, similar to how teams track operational costs in automated systems to catch structural issues early.
Data Contracts and Streaming Architectures
Contracts matter most where data moves continuously rather than in scheduled batches. In streaming systems, a producer and consumer are often deployed and scaled independently, sometimes by entirely different teams, which removes any natural synchronization point where a breaking change would be caught before it ships. This is also why contracts are frequently discussed alongside continuously generated data feeds, where a single producer’s output can silently retrain or mislead many automated downstream consumers if its structure or meaning drifts without warning. The same reasoning applies to sensitive domains such as proprietary or regulated data pipelines, where an unannounced change can create compliance exposure in addition to a technical outage.
- Data contract
- An explicit, enforced agreement between a data producer and its consumers covering schema, semantics, freshness, and change management.
- Schema registry
- A centralized service that stores canonical schemas for topics or services and rejects producers that publish incompatible messages.
- Backward compatibility
- A property of a schema change where new producer output can still be read correctly by consumers running an older version of the schema.
- Deprecation window
- A defined period between announcing a breaking change and retiring the old contract version, giving consumers time to migrate.
- Semantic versioning
- A convention for numbering contract versions so that consumers can tell at a glance whether a change is additive, compatible, or breaking.
- Contract testing
- Automated verification that a producer’s output and a consumer’s expectations still match, run in CI before a change is deployed.
Key Takeaways
- A data contract enforces schema, semantics, freshness, and ownership, not just documentation that people may forget to read.
- Schema registries such as Confluent Schema Registry and Buf enforce structural compatibility but do not capture business meaning on their own.
- Effective contracts are enforced automatically in CI and at runtime, not just written down once and left unmonitored.
- Every contract needs a named accountable owner and a documented process for proposing and approving changes.
- Breaking changes require a deprecation window so downstream teams have time to migrate before the old version disappears.
- Contracts matter most in streaming and event-driven systems, where producers and consumers deploy independently.
- Treating contract violations as hard CI failures, rather than warnings, produces measurably fewer production incidents.
FAQs
How is a data contract different from a schema registry?
A schema registry enforces structural compatibility of messages or tables, rejecting producers that publish incompatible formats. A data contract is broader: it also defines business semantics, freshness expectations, and a named owner, and typically uses a schema registry as one of its enforcement mechanisms rather than as a complete replacement.
Do data contracts only apply to streaming data?
No. While contracts are especially valuable in streaming systems because producers and consumers deploy independently, they apply equally to batch tables, APIs, and files exchanged between teams. Any interface where one team’s change can silently affect another team’s pipeline benefits from an enforced contract.
Who should own a data contract inside an organisation?
The producing team should own the contract, since they control the source system and are best positioned to know when a change is coming. Ownership should be assigned to a specific team or role with a documented escalation path, not left ambiguous across a shared backlog.
What tools are commonly used to enforce data contracts?
Common building blocks include Confluent Schema Registry for Kafka based systems, Buf for Protocol Buffers and gRPC, dedicated data contract frameworks that layer semantics and ownership metadata on top of a registry, and CI pipeline checks that validate compatibility before deployment.
What happens when a contract is violated?
In a well-enforced setup, a violation fails the producer’s build or deployment before the change reaches production. In systems relying only on runtime monitoring, a violation instead triggers an alert to both the producer and affected consumer teams so they can respond before the anomaly spreads further downstream.
Can data contracts slow down a fast-moving engineering team?
Well-designed contracts add checks in CI rather than manual approval steps, so additive and backward-compatible changes ship without friction. The only changes contracts intentionally slow down are breaking ones, which is the exact category of change that causes expensive incidents if it ships unchecked.
How do data contracts relate to data quality monitoring?
Data quality monitoring checks the values inside data after it lands, catching issues like unexpected nulls or outliers. Data contracts sit earlier in the lifecycle, preventing many of those issues by rejecting incompatible producer changes before they ship, so the two practices are complementary rather than interchangeable.
Do small engineering teams need formal data contracts?
Even a two-team setup benefits once one team’s data feeds another’s pipeline in production, since informal communication breaks down as soon as either team grows or priorities shift. Starting with a lightweight schema registry and a documented owner is usually enough before scaling up to fuller contract tooling.
- Confluent, “Schema Registry Overview,” Confluent Documentation.
- Buf Technologies, “Buf Schema Registry Documentation,” buf.build Documentation.
- Confluent, “Schema Evolution and Compatibility,” Confluent Documentation.
- Buf Technologies, “Breaking Change Detection,” buf.build Documentation.