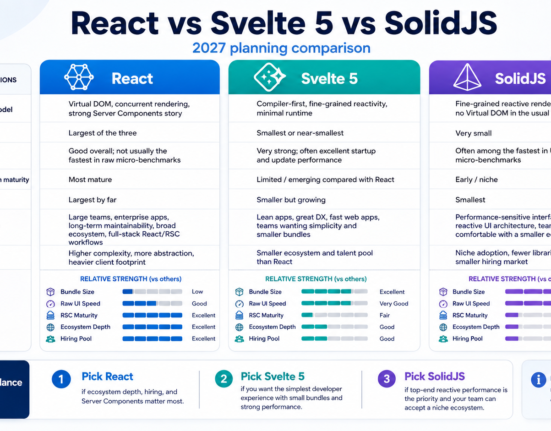
| Language/runtime | Memory management | Typical latency profile | Where it wins |
|---|---|---|---|
| Rust (Tokio + Axum/Actix) | Compile-time ownership, no GC | Predictable, no GC pauses, near-C performance | Latency-critical proxies, high-throughput services, systems-level infra |
| Go | Garbage collected (low-latency GC) | Very good, occasional small GC pauses | Fast-to-write concurrent services, strong standard library, simpler hiring |
| Node.js | Garbage collected (V8) | Good for I/O-bound work, weaker for CPU-bound | Rapid iteration, JS-everywhere teams, I/O-heavy APIs |
| Java (Spring, Micronaut) | Garbage collected (JVM, tunable) | Strong once JIT-warmed; startup and GC tuning matter | Large enterprise systems, mature tooling, huge existing codebases |
Why Rust Keeps Showing Up in Backend Conversations
Rust spent years being associated mostly with systems programming and, in tech-blog shorthand, with blockchain and cryptography projects drawn to its safety guarantees. By 2027, that association has broadened substantially. Rust now shows up in mainstream backend and API service conversations for a specific, narrow reason: it’s the rare language that offers both C-like performance and memory safety without a garbage collector, which matters a great deal for a specific slice of backend workloads — proxies, real-time infrastructure, and anything where a GC pause translates directly into a user-visible latency spike.
The honest framing matters here. Rust is not displacing Go, Node, or Java as a default backend choice — it’s being adopted selectively, for the services where the tradeoffs of a steeper learning curve and slower initial development are worth it. Understanding when that tradeoff pays off, rather than reaching for Rust everywhere, is the actual skill. That same broader shift toward distributed, cost-conscious infrastructure is documented in wider cloud software adoption data, where CPU and memory efficiency increasingly show up as line items worth engineering around, not just abstract benchmarks.
The Async Runtime: Tokio
Rust’s standard library deliberately doesn’t ship an async runtime, leaving that choice to the ecosystem — and Tokio has become the dominant answer, described in its own documentation as a runtime for writing reliable asynchronous applications, providing async I/O, a multi-threaded task scheduler, networking primitives (TCP/UDP), timers, and synchronization utilities. Tokio’s scheduler multiplexes many concurrent tasks onto a small pool of OS threads using non-blocking I/O backed by the operating system’s native event notification mechanism (epoll on Linux, kqueue on BSD/macOS, IOCP on Windows), which is what lets a single Rust service handle tens of thousands of concurrent connections without spawning a thread per connection.
In practice, adopting Tokio is close to mandatory for any real-world async Rust backend: essentially every popular Rust web framework (Axum, Actix Web, Warp) either runs on Tokio directly or is compatible with it, so choosing a framework and choosing to use Tokio are almost the same decision. What Tokio buys a backend team specifically is the elimination of an entire class of problems that plague garbage-collected runtimes under load — there’s no stop-the-world pause waiting to happen, because there’s no garbage collector; memory is freed deterministically as values go out of scope, checked entirely at compile time by Rust’s ownership system.
Choosing a Web Framework: Axum vs Actix Web
The two dominant HTTP frameworks in the Rust ecosystem take different design bets. Actix Web, built on the actor model, has topped raw throughput benchmarks for years and continues to post excellent numbers — independent 2026 benchmarks show Actix Web handling roughly 10-15% more requests per second than Axum under heavy saturation load (on the order of 20,000 vs 18,000 requests per second in one commonly cited comparison). Axum, built by members of the Tokio team, trades a small amount of that raw throughput for composability: every handler is a plain async function, and middleware is built on Tower’s service abstraction, which gives Axum a notably gentler learning curve and better integration with the wider Tokio ecosystem.
For most teams building a typical CRUD or data API in 2027, the throughput gap between the two frameworks is smaller than the gap between “a team productive in Axum” and “a team fighting Actix Web’s actor model for the first time.” That’s reflected in adoption trends: Axum has become the fastest-growing Rust web framework, closing the download-count gap with Actix Web and, in some recent months, surpassing it — largely on the strength of ergonomics rather than a throughput advantage. The pragmatic default for most new projects in 2027 is Axum unless a specific, measured throughput requirement points to Actix Web. Much of this tooling maturity traces back to the same open-source web development tools culture that has driven rapid iteration across the whole backend ecosystem, not just Rust specifically.
Figure 1: Axum vs Actix Web, Practical Tradeoff
Actix Web: ~20,000 req/s at saturation in common benchmarks, actor-model architecture, steeper learning curve, longest track record. Axum: ~18,000 req/s at saturation, plain-function handlers built on Tower middleware, gentler learning curve, fastest-growing adoption as of 2026-2027. The ~10-15% throughput gap rarely determines the right choice for typical API workloads; team familiarity and ecosystem fit usually do.
Benchmark figures as commonly reported in 2026 independent Rust web framework comparisons; actual results vary by workload, hardware, and configuration.
Real Production Case Studies
The case for Rust in backend services isn’t theoretical — two of the most cited examples come from Discord and Cloudflare, at very different layers of the stack. Discord rewrote its Read States service (which tracks which messages a user has read, one of the most frequently hit paths in the entire platform) from Go to Rust specifically because the Go version suffered latency spikes tied to Go’s garbage collector and memory model under sustained load. Because Rust has no garbage collector, that entire class of latency spike disappeared, and Discord reported meaningfully more consistent tail latency after the rewrite — alongside Discord’s separate, larger-scale use of Rust and Elixir NIFs to help scale real-time infrastructure to millions of concurrent users.
Cloudflare’s case study operates at an even larger scale: Pingora, Cloudflare’s Rust-based proxy that replaced large parts of its NGINX-based infrastructure, now handles over one trillion requests per day. Cloudflare has reported that the switch delivered roughly 70% less CPU consumption and 67% less memory usage compared to the prior NGINX/Lua stack, along with a 5ms median latency improvement and an 80ms improvement at the p95 percentile. Connection reuse for one major customer improved from 87.1% to 99.92%, which Cloudflare estimated eliminated the equivalent of 434 years of aggregate TLS handshake time daily across all customers on the platform. Both case studies point to the same underlying mechanism: removing garbage collection and unsafe-by-default memory handling doesn’t just prevent crashes, it removes entire categories of performance variance that are otherwise very difficult to engineer around in a GC’d language — the same kind of infrastructure-efficiency gain that broader industry coverage of cloud computing’s impact on IT has tracked at a macro level for years.
When the Tradeoff Is Actually Worth It
Rust’s cost is real and shouldn’t be minimized: slower initial development velocity, a genuinely steep learning curve around ownership and borrowing for engineers coming from garbage-collected languages, longer compile times, and a smaller (though rapidly growing) pool of engineers who already know the language well. Choosing Rust for a service where none of its advantages actually matter is a self-inflicted tax. The tradeoff earns its keep specifically when a service sits on a hot path where GC pauses are directly visible to users or other systems (a proxy, a real-time messaging backend, a matching engine), when memory footprint at scale has a direct cost (Cloudflare’s 67% memory reduction across a global edge network is a real infrastructure bill, not an academic number), or when the team is already comfortable with Rust and the marginal cost of writing a new service in it is lower than for a team starting fresh.
This is the same category of decision teams already make when picking a hosting and compute model for a REST API on API Gateway and Lambda versus a long-running service — the right answer depends entirely on the specific latency, cost, and scale constraints of the workload in front of you, not a blanket preference.
| Signal | Points toward Rust | Points toward Go/Node/Java |
|---|---|---|
| Latency sensitivity | GC pauses are directly user-visible or cascade into SLA breaches | Occasional GC pauses are acceptable or already well-tuned |
| Team Rust experience | Team already productive in Rust | Team would need significant ramp-up time |
| Time to first working service | Less critical than long-term performance/cost | Speed to ship matters more than peak throughput |
| Infrastructure cost at scale | CPU/memory footprint directly drives infrastructure spend | Current footprint is not a binding cost constraint |
| Ecosystem/library maturity needed | Core need is covered by Tokio/Axum/Actix ecosystem | Needs a specific mature library only available elsewhere |
Adopting Rust for a Service Without Betting the Company
- Step 1. Identify the actual hot path. Pick one service where latency, CPU, or memory cost is measurably a problem today, not a hypothetical future one.
- Step 2. Prototype the rewrite in isolation. Build the new Rust service behind the same interface as the existing one so it can be swapped in without a wider architecture change.
- Step 3. Choose Axum unless you have a measured reason not to. Default to the framework with the gentler learning curve; only reach for Actix Web if a specific throughput requirement demands it.
- Step 4. Benchmark against the real production baseline. Compare tail latency (p95, p99) and resource usage against the existing service under real traffic patterns, not synthetic load alone.
- Step 5. Budget real ramp-up time for the team. Ownership and borrowing take longer to internalize than a new framework’s API surface; plan weeks, not days.
- Step 6. Roll out behind a flag and compare. Run old and new services side by side against production traffic before fully committing, mirroring how Discord and Cloudflare validated their rewrites before full cutover.
Common mistakes
- Choosing Rust for a service with no measured latency or resource problem, paying the learning-curve cost for no real benefit.
- Underestimating onboarding time for engineers new to ownership, borrowing, and lifetimes, then blowing through project timelines.
- Picking Actix Web for its raw benchmark numbers on a project where the actor-model learning curve slows the team down more than the throughput gain helps.
- Rewriting an entire system at once instead of isolating one hot-path service first, the way both Discord and Cloudflare’s most-cited case studies did.
- Ignoring compile times in CI pipeline planning — Rust’s compile times are longer than Go’s or Node’s iteration loop and need to be budgeted for.
- Assuming memory safety alone is worth the switch without also confirming a genuine performance or reliability requirement exists.
In practice
Teams that adopt Rust successfully for backend services almost always start with a single, well-instrumented service rather than a platform-wide migration. The common pattern mirrors what both Discord and Cloudflare did publicly: identify one service where the current language’s runtime characteristics (GC pauses, memory footprint) are a measured, not theoretical, problem; rewrite that one service behind its existing API contract; and validate the rewrite against real production traffic before expanding scope. Teams also invest early in developer experience — clear onboarding docs for ownership and borrowing, a shared set of Tokio and Axum conventions, and CI pipelines tuned for Rust’s longer compile times — because the biggest realistic risk to a Rust adoption isn’t the language’s runtime behavior, it’s a team’s ramp-up curve turning into stalled projects. This mirrors the same measured, incremental discipline that shows up in broader backend re-architecture efforts, where isolating one service at a time is consistently what separates successful migrations from stalled ones.
Glossary
- Ownership and borrowing
- Rust’s compile-time memory management model that tracks which part of a program owns a value and enforces safe access rules without a runtime garbage collector.
- Tokio
- The dominant asynchronous runtime for Rust, providing a task scheduler, non-blocking I/O, timers, and synchronization primitives for building concurrent network services.
- Axum
- A Rust web framework built by the Tokio team, using plain async functions as handlers and Tower’s service abstraction for middleware.
- Actix Web
- A high-throughput Rust web framework built on the actor model, known for consistently strong raw benchmark performance.
- Garbage collection (GC) pause
- A pause in program execution while a garbage-collected runtime reclaims unused memory, which can introduce unpredictable latency spikes under load.
- Pingora
- Cloudflare’s Rust-based proxy framework that replaced much of its NGINX-based infrastructure, handling over a trillion requests per day.
- Tail latency (p95/p99)
- The response time experienced by the slowest 5% or 1% of requests, often the metric most affected by GC pauses or resource contention.
- Actor model
- A concurrency model where independent “actors” communicate via message passing, used as the architectural foundation of Actix Web.
Key Takeaways
- Rust’s core backend value is memory safety and predictable performance without a garbage collector, not blanket superiority over Go, Node, or Java.
- Tokio is the near-universal async runtime underneath Rust’s web frameworks, enabling tens of thousands of concurrent connections without a thread-per-connection model.
- Axum trades a small amount of raw throughput for ergonomics and is the pragmatic default; Actix Web wins on raw benchmarks but has a steeper learning curve.
- Discord’s Read States rewrite eliminated Go-GC-related latency spikes; Cloudflare’s Pingora cut CPU use by ~70% and memory by ~67% at a trillion-requests-a-day scale.
- The tradeoff is worth it specifically when GC pauses are user-visible, when infrastructure cost scales with CPU/memory footprint, or when the team already knows Rust well.
- Successful adoptions isolate one measurably problematic service first rather than attempting a platform-wide rewrite.
- Rust’s real cost is ramp-up time and compile times, not runtime risk — budget for both explicitly rather than assuming a fast rollout.
FAQs
Is Rust always faster than Go for backend services?
Not universally, but it tends to have more predictable tail latency because it has no garbage collector. Go is already very fast for most workloads; Rust’s advantage shows up most clearly under sustained high load or when GC pauses are directly user-visible.
Should I choose Axum or Actix Web for a new project?
Default to Axum unless you have a specific, measured throughput requirement. Axum’s plain-function handlers and Tower-based middleware give it a gentler learning curve, and independent benchmarks show only a 10-15% throughput gap versus Actix Web under heavy load.
What made Discord rewrite a service from Go to Rust?
Discord’s Read States service, one of its most frequently accessed paths, suffered latency spikes tied to Go’s garbage collector and memory model under sustained load. Rewriting it in Rust removed garbage collection entirely, eliminating that class of latency spike.
What is Cloudflare’s Pingora and why does it matter?
Pingora is Cloudflare’s Rust-based proxy that replaced much of its NGINX/LuaJIT infrastructure, now handling over a trillion requests per day with reported reductions of roughly 70% in CPU usage and 67% in memory usage versus the prior stack.
Does Rust’s steep learning curve make it a bad choice for smaller teams?
Not necessarily, but it’s a real cost to budget for. Smaller teams should weigh whether the specific service actually needs Rust’s performance and safety guarantees, since the ramp-up time is proportionally more expensive for a small team than a large one.
Can Rust be used for typical CRUD APIs, not just high-performance infrastructure?
Yes — frameworks like Axum make typical REST/CRUD APIs straightforward to build in Rust, though for most CRUD-style workloads without extreme latency or scale requirements, Go or Node may ship faster with comparable practical performance.
What is Tokio and do I need to use it directly?
Tokio is Rust’s dominant async runtime, providing the scheduler and non-blocking I/O that async Rust code needs to run. Most developers use it indirectly through a web framework like Axum or Actix Web rather than calling Tokio’s APIs directly for everyday application code.
How should a team measure whether a Rust rewrite was worth it?
Compare tail latency (p95/p99), CPU and memory usage, and incident rate against the original service’s production baseline under real traffic, the same way Discord and Cloudflare validated their respective rewrites before fully committing to them.
References
- Tokio Documentation, official site — https://tokio.rs/
- Tokio API Documentation, docs.rs — https://docs.rs/tokio
- Axum Documentation, GitHub — https://github.com/tokio-rs/axum
- Cloudflare Blog, “Cloudflare just got faster and more secure, powered by Rust” — https://blog.cloudflare.com/20-percent-internet-upgrade/
- Corrode Rust Consulting, “Rust in Production: Cloudflare” podcast — https://corrode.dev/podcast/s05e03-cloudflare/