| Myth | Reality |
|---|---|
| You need a frontier closed model like GPT-4V to get usable document extraction accuracy. | Open models such as Qwen2.5-VL and InternVL3 now match GPT-4o-class performance on many document benchmarks once fine-tuned on task-specific data. |
| Fine-tuning a vision-language model requires full-parameter training on large GPU clusters. | LoRA and QLoRA adapt multimodal models on a single consumer or mid-range cloud GPU by training small low-rank adapters instead of all the weights. |
| Document layout information gets lost once a page becomes an image input. | Layout-aware fine-tuning datasets explicitly encode bounding boxes and reading order so the model learns spatial structure, not just pixel content. |
| One generic fine-tune can handle invoices, receipts, and chart QA equally well. | Each document task benefits from its own curated dataset and prompt format, since the visual patterns and expected output schemas differ substantially. |
Vision-language models have crossed a practical threshold. It is no longer necessary to call an expensive, closed, general-purpose multimodal API for every document understanding task. A model like Qwen2.5-VL, LLaVA, or InternVL3, fine-tuned on a few thousand examples of the specific document type a business actually processes, frequently outperforms a generic frontier model prompted zero-shot, at a fraction of the ongoing inference cost. This piece is a practical walkthrough of how that fine-tuning actually happens: which base models to start from, how LoRA and QLoRA make the training affordable, how to prepare document datasets so the model actually learns layout and not just text, and where the current limits are.
Why Fine-Tune Instead of Prompting a Frontier Model
Prompting GPT-4V-class or Gemini-class models with document images works well for prototyping, but it has three costs that scale badly for production document pipelines: per-call API pricing that adds up fast at high volume, latency that is often too slow for real-time processing pipelines, and no ability to guarantee output schema consistency without heavy prompt engineering and retries. Fine-tuning trades a one-time training cost for a model that is cheaper, faster, and more predictable to run at inference time, and that can be hosted entirely inside a company’s own infrastructure when data privacy rules require it.
Open-source vision-language models have closed the capability gap enough that this tradeoff now makes sense for far more teams than it did two years ago. Qwen2.5-VL, in both its 2B and 7B parameter variants, along with Llama-3.2-Vision, Gemma 3, and InternVL3, have all shown strong results on document benchmarks once fine-tuned on domain-specific data, and evaluations comparing multiple open models on custom-annotated frames have found that mid-sized 7B-class models can match or exceed the accuracy of much larger closed alternatives on narrow tasks.
Choosing a Base Model
| Base model family | Best fit | Notes |
|---|---|---|
| Qwen2.5-VL (2B / 7B / 72B) | Production document extraction and OCR | Strong layout understanding out of the box; widely used as a fine-tuning base in 2026 |
| LLaVA family | Rapid prototyping | Simple to fine-tune and well documented, but weaker on dense document layouts than Qwen-VL or InternVL |
| InternVL3 | Production with data privacy requirements | Competitive with closed models on chart and table QA benchmarks |
| GPT-4V-class / Gemini (closed) | Prototyping, low-volume, or zero-shot baseline | Cannot be self-hosted or fine-tuned in the same open way; useful as an evaluation baseline |
LoRA and QLoRA for Multimodal Models
Low-Rank Adaptation (LoRA) freezes the base model’s weights and injects small trainable low-rank matrices into specific layers, typically the attention projections, so that only a tiny fraction of the total parameter count is ever updated. For a 7-billion-parameter vision-language model, this can mean training well under 1 percent of the total parameters while still achieving competitive task performance, because the frozen base model already encodes strong general visual and language understanding — fine-tuning only needs to steer that understanding toward a specific task and output format.
QLoRA extends this further by loading the frozen base model in 4-bit quantized precision, cutting memory usage by roughly 75 percent compared to standard 16-bit loading, while still training the LoRA adapters in higher precision on top. This is what makes fine-tuning a 7B-class vision-language model feasible on a single consumer-grade or mid-range cloud GPU rather than requiring a multi-GPU cluster. Frameworks such as Unsloth have further optimized this pipeline specifically for popular open vision-language models, reducing both memory footprint and wall-clock training time compared to a naive QLoRA implementation.
For multimodal models specifically, an important detail is deciding whether to apply LoRA adapters only to the language-model backbone, only to the vision encoder, or to both. Most document fine-tuning recipes apply adapters primarily to the language-model side and the cross-attention or projection layers that connect vision features to the language model, since the vision encoder’s low-level feature extraction is usually already well suited to document images without further adaptation. Adapting the vision encoder as well can help for unusual document types, such as handwritten forms or very low-resolution scans, but adds training cost and risk of overfitting on small datasets.
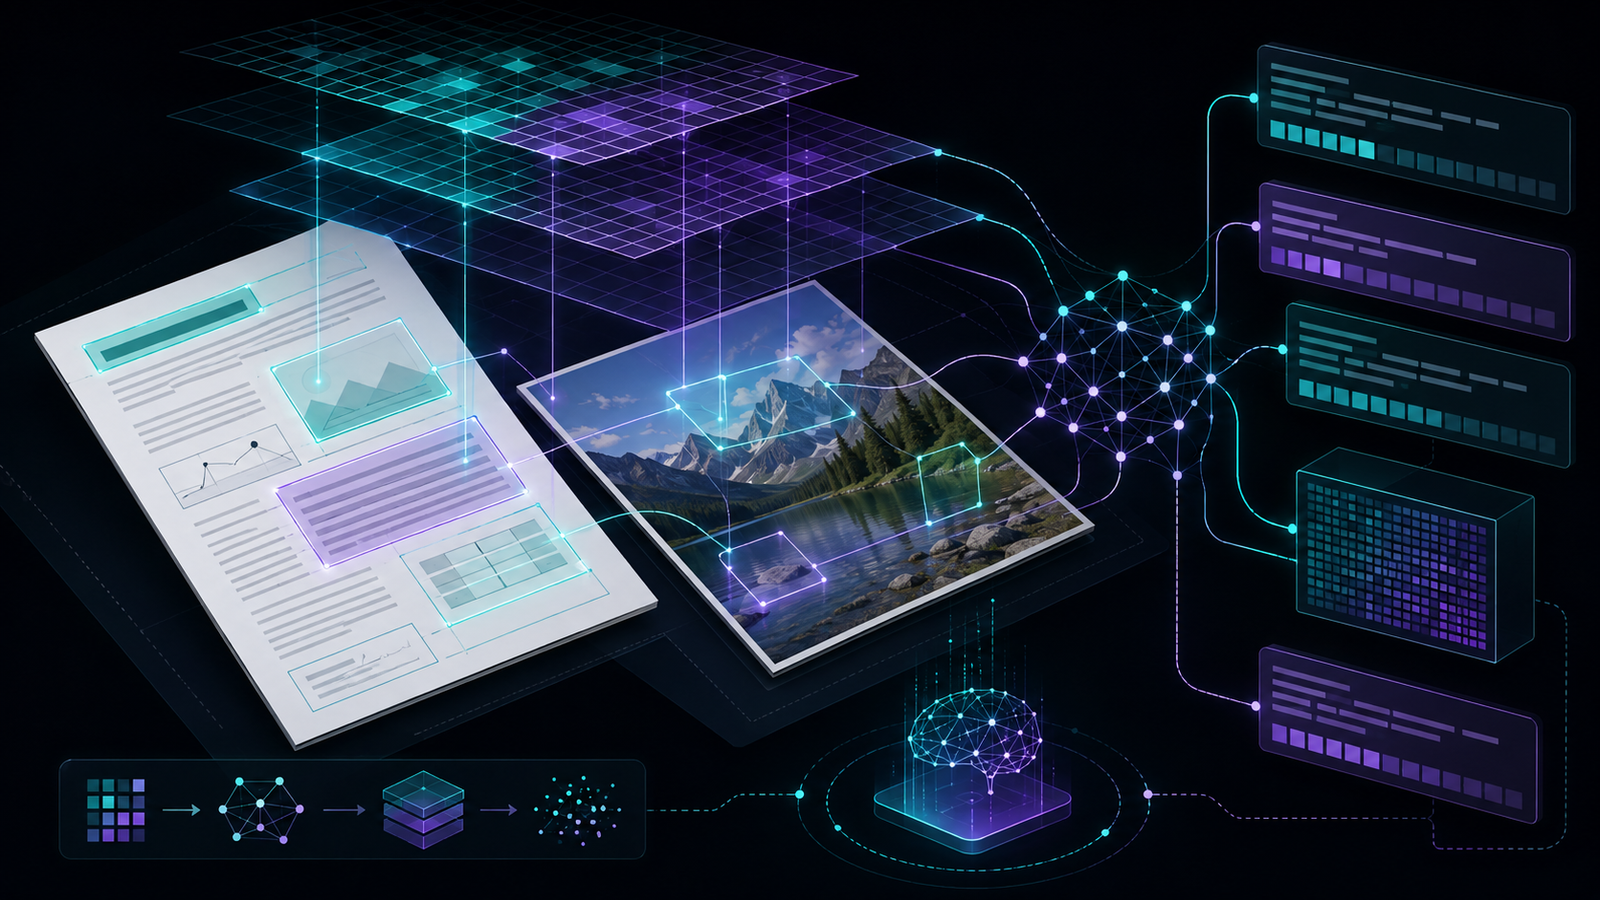
Where LoRA adapters attach in a vision-language model
The frozen vision encoder produces image features, which pass through a projection layer into a frozen language-model backbone; LoRA adapters are inserted into the language model’s attention layers and often the projection layer, leaving the bulk of both networks untouched during fine-tuning.
Preparing Document Datasets
Data preparation is where most document fine-tuning projects actually succeed or fail, more so than model or hyperparameter choice. Three practical needs come up repeatedly:
- Layout-aware annotation. Rather than only pairing an image with a plain-text transcription, effective datasets include structured targets — bounding boxes, reading order, or a markup format like Markdown or JSON that preserves table structure and field positions — so the model learns to output structured data rather than a flat text dump.
- Task-matched output schema. An invoice extraction task should train on outputs shaped exactly like the schema downstream systems expect (vendor name, line items, totals, tax fields), rather than open-ended natural-language descriptions, since consistent schema training reduces the need for brittle post-processing parsers.
- Realistic visual noise. Training sets that only include clean, high-resolution scans tend to fail in production, where real documents arrive as skewed phone photos, low-contrast faxes, or partially cropped images. Synthetic augmentation — rotation, blur, compression artifacts, lighting variation — closes much of this gap without needing to collect thousands of real messy scans.
Recent fine-tuning work on document-to-markdown generation, for example, has used datasets pairing scanned document pages directly with ground-truth Markdown, which preserves headings, tables, and lists in a format both human-readable and easy to parse programmatically downstream — a good default target format for general document digitization tasks.
Task-Specific Considerations
Invoice and Receipt Extraction
These tasks benefit from strict output schemas and from training data that spans many vendor layouts, since invoice formats vary enormously between issuers. A model fine-tuned only on one company’s invoice template will not generalize to a new vendor’s layout without additional data.
Layout-Aware OCR
General OCR fine-tuning benefits from including reading-order supervision, especially for multi-column documents, forms with disconnected fields, and documents mixing printed and handwritten text, since naive left-to-right, top-to-bottom OCR often scrambles multi-column layouts.
Chart and Table QA
Chart and table question-answering requires the model to reason over visual structure, not just extract text — for example, comparing bar heights or summing a table column. Fine-tuning datasets for this task typically include question-answer pairs grounded in the chart’s actual data, and evaluations have shown that fine-tuned mid-sized open models can approach closed frontier model accuracy on these reasoning-heavy visual QA benchmarks.
| Document task | Training data volume (typical) | Key data requirement |
|---|---|---|
| Invoice / receipt extraction | 5,000-20,000 examples | Wide vendor layout diversity, strict schema targets |
| Layout-aware OCR | 10,000-50,000 examples | Reading-order and bounding-box supervision |
| Chart / table QA | 5,000-15,000 QA pairs | Questions grounded in actual chart or table data |
| Document-to-Markdown digitization | 1,000-10,000 page pairs | Clean Markdown ground truth preserving structure |
Common Pitfalls in Practice
Common mistake
Teams frequently fine-tune on a dataset of clean, high-resolution scans and then deploy against real-world phone-camera photos or faxed documents, causing a sharp accuracy drop in production that never showed up in evaluation. Including realistic visual noise and low-quality examples in both training and test sets is the fix, not just in training data alone.
What worked
A finance operations team fine-tuned Qwen2.5-VL-7B with QLoRA on roughly 12,000 annotated invoices spanning 40 different vendor layouts, training adapters only on the language-model attention layers and projection layer. The fine-tuned model matched a closed frontier model’s field-extraction accuracy on held-out vendors while cutting per-document inference cost by more than 80 percent, since the fine-tuned model could be self-hosted rather than billed per API call.
Frequently Overlooked Details
- Adapter placementApplying LoRA to the wrong layers wastes capacity; language-model attention and vision-language projection layers are usually the highest-value targets for document tasks.
- Resolution mismatchFine-tuning on downsized images when production documents arrive at higher resolution silently discards fine text detail the model never learns to read.
- Evaluation format sensitivityExact-match scoring against structured outputs can unfairly penalize semantically correct answers with minor formatting differences; field-level scoring is usually more informative.
- Catastrophic forgetting of general abilityAggressive fine-tuning can degrade a model’s general visual reasoning even as narrow task accuracy improves; a small held-out general-purpose benchmark catches this early.
- Quantization accuracy loss4-bit QLoRA training occasionally introduces small accuracy regressions versus full-precision LoRA on the hardest examples; worth checking before committing to QLoRA at scale.
Evaluating Fine-Tuned Multimodal Models
Standard text-only evaluation metrics are insufficient for document tasks because layout and structure matter as much as text content. Field-level accuracy (did the model extract the right value for the right field), structural fidelity (did table rows and columns stay aligned), and end-to-end task success rate (would the extracted data pass downstream validation without manual correction) are the three metrics that matter most in production. Building a rigorous evaluation harness for these dimensions is closely related to the broader discipline covered in our guide to LLM evaluation frameworks, and the same reproducibility discipline described in our piece on reproducible ML applies directly to multimodal fine-tuning runs, where small data or seed changes can shift results meaningfully.
Glossary
- LoRA (Low-Rank Adaptation)
- A parameter-efficient fine-tuning method that trains small low-rank matrices inserted into a frozen model’s layers instead of updating all parameters.
- QLoRA
- A variant of LoRA that loads the frozen base model in 4-bit quantized precision to reduce memory usage during fine-tuning.
- Vision-language model (VLM)
- A model architecture that processes both images and text jointly, typically combining a vision encoder with a language-model backbone.
- Layout-aware OCR
- Optical character recognition that preserves spatial structure such as reading order, columns, and table alignment, rather than extracting text as an unstructured stream.
- Catastrophic forgetting
- The loss of a model’s previously learned general capabilities as a side effect of narrow fine-tuning on a specific task.
Key Takeaways
- Open vision-language models like Qwen2.5-VL and InternVL3 now match closed frontier models on many document tasks once fine-tuned.
- LoRA and QLoRA make fine-tuning feasible on a single GPU by training a small fraction of total parameters.
- Applying adapters to the language-model attention and projection layers is usually higher value than adapting the vision encoder.
- Layout-aware, schema-matched training data matters more to final accuracy than model choice or hyperparameters.
- Realistic visual noise in training data is essential, since clean-scan-only datasets fail against real-world document quality.
- Document task evaluation needs field-level and structural metrics, not just text-similarity scores.
- Fine-tuned self-hosted models can cut per-document inference cost dramatically compared to closed API pricing at scale.
FAQs
What is multimodal model fine-tuning?
Multimodal fine-tuning adapts a pretrained vision-language model to a specific task, such as document extraction or chart QA, by further training it on task-specific image-text pairs, usually using parameter-efficient methods like LoRA rather than updating all weights.
Which base models work best for document understanding?
Qwen2.5-VL and InternVL3 are currently strong choices for document tasks due to their layout understanding, while LLaVA remains a popular option for fast prototyping despite being somewhat weaker on dense document layouts.
How much data is needed to fine-tune a vision-language model for documents?
Most production document fine-tuning projects use between 5,000 and 50,000 labelled examples, though smaller datasets of 1,000-2,000 examples can work for narrower tasks like single-template document digitization.
What is the difference between LoRA and QLoRA?
LoRA trains small low-rank adapter matrices on top of a frozen full-precision base model, while QLoRA additionally loads that frozen base model in 4-bit quantized form, cutting memory usage substantially at a small potential accuracy cost.
Can fine-tuning replace frontier closed models entirely?
For narrow, well-defined document tasks, yes — fine-tuned open models frequently match or exceed closed frontier model accuracy while being cheaper and faster to run, though closed models remain useful as zero-shot baselines and for highly varied general-purpose tasks.
Why does document layout matter for fine-tuning?
Documents encode meaning through spatial position, such as table columns or form fields, and models trained only on flat text transcriptions lose this structure, producing outputs that scramble multi-column or tabular content.
What causes fine-tuned document models to fail in production?
The most common cause is a training set of only clean, high-resolution scans that does not represent the visual noise of real-world documents such as phone photos, skewed scans, or compression artifacts.
How should teams evaluate a fine-tuned vision-language model?
Field-level extraction accuracy, structural fidelity for tables and layouts, and end-to-end downstream task success rate matter more than generic text-similarity metrics for document-focused multimodal models.
Teams building document pipelines alongside broader ML infrastructure may also find our guides on feature stores and model monitoring in production useful for keeping fine-tuned multimodal models healthy after deployment. For teams weighing labelling strategy before a fine-tuning run, our piece on active learning covers how to prioritize which documents get annotated first, and our guide to MLOps in the LLM era covers the broader operational picture these fine-tuned models fit into.
- Medium, “Fine-Tuning a Vision Language Model for Document-to-Markdown Generation: A Complete Guide”
- Medium, “Efficient Fine-Tuning of Vision Language Models (VLMs) with LoRA and Quantization”
- Label Your Data, “VLM: How Vision-Language Models Work (2026 Guide)”
- Frontiers in Artificial Intelligence, “Resource-efficient fine-tuning of large vision-language models for multimodal perception in autonomous excavators”
- Medium, “Fine-Tuning Qwen3-VL: A Practical Guide for Vision-Language Model Adaptation”