| Myth | Reality |
|---|---|
| A GNN fraud model is just a fancier version of a per-transaction classifier | It changes the unit of analysis from a single transaction to a neighborhood of accounts and transfers, so it can surface coordinated rings that never trip a single-transaction rule |
| More graph hops always means better fraud detection | Beyond two or three hops, message passing tends to over-smooth node representations, blurring the exact signal that made a fraud ring detectable in the first place |
| Labeled fraud data is roughly as available as labeled data in other ML domains | Confirmed fraud labels typically cover well under one percent of transactions, arrive months after the fact, and are heavily biased toward whatever the current rules engine already flags |
| A GNN model, once trained, keeps working the way it did at launch | Fraud rings actively probe and adapt their structure specifically to evade whatever detection pattern is currently in production, so performance decays without deliberate retraining cycles |
Why Fraud Teams Turned to Graphs
A conventional fraud classifier looks at one transaction at a time: amount, merchant category, device fingerprint, time of day, and a handful of engineered aggregates like “spend in the last 24 hours.” That approach is fast and it catches a lot of unsophisticated fraud, but it is structurally blind to coordination. A money-laundering ring or a synthetic-identity fraud network is, almost by definition, a pattern that only shows up when you look at how accounts, devices, and transfers connect to each other. A graph neural network, or GNN, is built specifically to learn from that connectivity, treating accounts and transactions as nodes and edges in a network rather than as independent rows in a table, and letting the model propagate information along those connections to flag not just a suspicious transaction but a suspicious neighborhood.
This matters most in the two domains where per-transaction rules consistently underperform: anti-money-laundering, where a ring deliberately structures many small, individually unremarkable transfers to move money through a chain of accounts, and coordinated fraud rings, where dozens of seemingly unrelated accounts share a device, an IP range, or a beneficiary account that a row-by-row model has no way of connecting.
A Brief Primer on Message Passing
At a mechanical level, a GNN works by repeatedly updating each node’s representation using information aggregated from its neighbors, a process usually called message passing. After one round, a node knows something about its immediate neighbors; after two rounds, it indirectly knows about neighbors of neighbors, and so on. Architectures like Graph Convolutional Networks and GraphSAGE differ mainly in how they aggregate that neighbor information and whether they can generalize to nodes never seen during training. This piece assumes that background rather than re-deriving it in depth, since the fundamentals of message passing, GCNs, and GraphSAGE are covered thoroughly in general GNN introductions; what follows is specific to how those fundamentals get adapted for financial-crime graphs, which look and behave very differently from the citation networks or molecule graphs those fundamentals are usually taught on.
Building the Transaction Graph: Nodes, Edges, and Feature Design
The single most consequential design decision in a fraud GNN is not the architecture, it is how the graph itself is constructed, because a badly designed graph gives even the best architecture nothing useful to propagate. Financial transaction graphs are typically heterogeneous, meaning they contain more than one type of node and edge, which is a meaningful departure from the homogeneous graphs used in most GNN tutorials.
Node Types That Actually Carry Signal
- Accounts. Carry features like account age, KYC verification status, historical transaction volume, and risk tier.
- Devices and IP addresses. Shared devices or IP ranges across accounts that claim to be unrelated are one of the strongest fraud ring signals available, and only a graph representation makes this queryable at scale.
- Merchants or beneficiaries. Especially in card-not-present fraud and first-party fraud, the receiving side of a transaction carries as much signal as the sending side.
- Transactions themselves as edges or as nodes. Some architectures model a transaction as an edge connecting two accounts with the amount and timestamp as edge features; others model it as its own node connected to both parties, which allows richer transaction-level features but increases graph size substantially.
Edge Construction Choices
Edges can represent direct transfers, shared-device relationships, shared-address relationships, or even statistical similarity between account behavior profiles. Each choice changes what the model can detect. A graph built only on direct transfer edges will miss a ring that never transacts directly with itself but shares devices; a graph that adds device- and IP-sharing edges catches that pattern but at the cost of a much denser, more expensive graph to compute over.
| Graph element | What it captures | Detection strength | Cost or risk |
|---|---|---|---|
| Account-to-account transfer edges | Direct money movement between parties | Strong for layering and structuring patterns | Misses rings that avoid transacting directly |
| Shared device or IP edges | Coordination between accounts that never transact together | Strong for mule networks and synthetic identity rings | Higher false-positive rate from shared household or NAT’d IPs |
| Transaction-as-node representation | Rich per-transaction features (amount, channel, timestamp) | Better fine-grained scoring | Substantially larger graph, higher compute and memory cost |
| Behavioral similarity edges | Accounts with statistically similar spending patterns | Useful for first-party and application fraud | Requires a separate similarity model, adds a maintenance layer |
GraphSAGE and Inductive Learning for Unseen Accounts
Financial graphs are never static. New accounts are opened constantly, and a fraud model that can only score accounts it saw during training is close to useless in production. This is why GraphSAGE, and inductive GNN architectures generally, dominate this domain over transductive approaches. GraphSAGE learns aggregation functions rather than fixed per-node embeddings, so a brand-new account can be scored immediately by aggregating the features and connections of its neighbors, without retraining the model. That property, generalizing to nodes never seen during training, is arguably the single most important architectural requirement for a production fraud GNN, more important than any specific accuracy improvement a newer architecture might offer.
Temporal Graph Networks: Catching Rings as They Form
A static graph snapshot misses the fact that fraud rings unfold over time, often deliberately spacing transfers to stay under detection thresholds. Temporal graph networks extend message passing to incorporate edge timestamps directly, so the model can learn patterns like “a burst of small transfers between the same cluster of accounts within a 48-hour window” rather than treating all historical transfers as equally relevant regardless of when they happened.
Recent published work illustrates the range of approaches. LAS-GNN, presented at the ACM International Conference on AI in Finance, is designed specifically to detect suspicious subgraph motifs in weighted temporal networks, using a directed message-passing mechanism compatible with edge timestamps to catch laundering-specific structural patterns rather than generic anomalies. Amatriciana takes a similar temporal-GNN approach to detecting money launderers inside large transaction graphs by explicitly weighting recency of activity. DELATOR frames the same problem as multi-task learning across large transaction graphs, jointly predicting multiple laundering-related labels rather than a single binary fraud flag, which tends to produce more robust representations when confirmed labels for any one task are sparse. A separate line of work applies heterogeneous graph attention networks across transaction flows, entity relationships, device linkages, and temporal interactions simultaneously, explicitly built for multi-layered anti-money-laundering detection and paired with explainability tooling so investigators can see which subgraph triggered an alert.
| Model or approach | Core mechanism | Best suited for |
|---|---|---|
| GraphSAGE (inductive baseline) | Learned neighbor aggregation, generalizes to unseen nodes | Any graph where new accounts appear continuously |
| LAS-GNN | Directed temporal message passing tuned to laundering motifs | Detecting structured transfer patterns within time windows |
| Amatriciana | Temporal GNN weighting transaction recency | Efficient, lower-latency laundering detection |
| DELATOR | Multi-task learning across large transaction graphs | Domains with very sparse confirmed labels |
| Heterogeneous GNN-XAI frameworks | Graph attention over multiple entity and relationship types plus explainability | Investigator-facing alerts that need a justification |
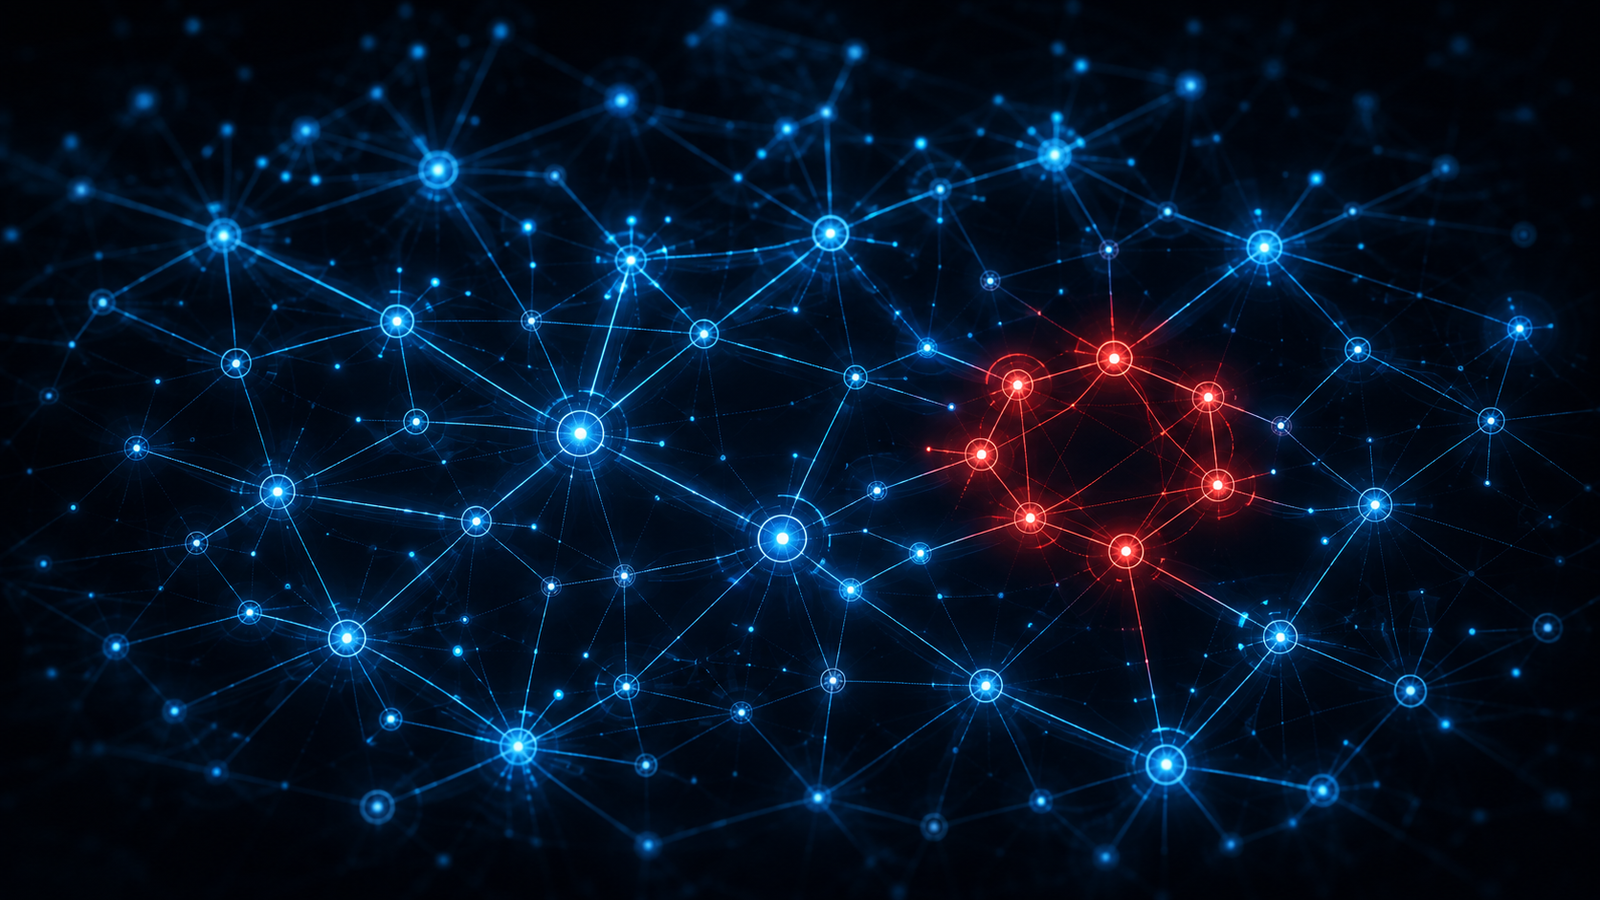
A laundering ring surfaced through shared-device and transfer edges
A cluster of accounts with unremarkable individual transaction histories becomes visibly anomalous once shared-device edges and a tight temporal transfer pattern are added to the graph, which is the exact structure a per-transaction classifier has no way to represent.
The Real Challenge: Label Scarcity
Confirmed fraud labels are rare, delayed, and biased. Rare, because even generous estimates put confirmed fraud well under one percent of transaction volume. Delayed, because a money-laundering investigation can take months to confirm, meaning the labels a model trains on today reflect fraud patterns from months or years earlier, not current ones. Biased, because most “confirmed fraud” labels originated from whatever rules-based system was already in place, meaning a model trained naively on those labels partly just learns to reproduce the existing rules engine rather than discovering new patterns. Teams working in this space lean heavily on multi-task learning, as DELATOR does, on semi-supervised approaches that propagate weak labels across the graph from a small confirmed set, and on unsupervised anomaly scoring layered on top of supervised signal to catch patterns the labeled data never represented at all.
Adversarial Adaptation by Fraudsters
Unlike most ML domains, fraud detection faces an adversary who is actively trying to defeat the specific model in production. Once a detection pattern becomes reliable, fraud rings restructure themselves specifically to avoid it, spacing transfers differently, rotating which accounts act as intermediaries, or deliberately maintaining low-connectivity “burner” accounts that never accumulate enough graph signal to trigger detection. This means a fraud GNN’s performance is not stable over time in the way an image classifier’s might be; it decays as adversaries adapt, and it requires an operating model built around continuous retraining and monitoring, not a train-once-deploy-forever assumption.
Real-Time Inference Latency Requirements
A card authorization decision typically has to happen in well under 100 milliseconds, and a payment network will not wait for a full graph traversal at inference time. This forces a split architecture in most production systems: expensive graph embedding computation happens offline or in near-real-time batch updates, producing a compact vector representation for each account that captures its graph neighborhood, while the actual authorization-time decision is a fast lookup against those precomputed embeddings combined with lightweight, transaction-specific features computed inline. Full end-to-end graph inference is generally reserved for post-transaction investigation queues and periodic batch re-scoring, not the authorization path itself.
Evaluating a Fraud GNN Beyond Raw Accuracy
Standard classification metrics are misleading in this domain because the cost of a false negative and a false positive are wildly asymmetric and because the positive class is so rare that a model can post excellent-looking accuracy while catching almost nothing. Teams instead lean on precision at a fixed alert-volume budget, since investigation teams can only manually review a finite number of flagged accounts per day regardless of how many the model surfaces, and on recall specifically within known fraud ring clusters rather than recall averaged across all fraud types, since ring detection is usually the entire point of adding a graph model in the first place.
Alert fatigue is the operational failure mode that kills otherwise-good fraud GNN deployments. If a graph model triples the volume of flagged accounts without a proportional increase in confirmed fraud among those flags, investigation teams start deprioritizing or rubber-stamping alerts, which quietly erodes the value of the entire system regardless of what the offline metrics say. This is why the explainability layer matters as much as raw detection lift: an alert that comes with a visualized subgraph showing exactly which shared device or transfer pattern triggered it gets investigated faster and more accurately than a bare risk score, and several of the heterogeneous GNN-XAI frameworks referenced above were built specifically to close that gap between model output and investigator action.
Finally, teams need a deliberate policy for how a graph model’s score interacts with the existing rules engine rather than silently replacing it. Most production deployments run the GNN score as an additional signal alongside existing rules for a substantial evaluation period, comparing where the two disagree, before allowing the graph model to independently trigger a hold or decline, precisely because a graph model failure mode, like a false positive triggered by a shared household IP, looks very different from a rules-engine failure mode and needs its own escalation path.
Common mistake
Teams building a first fraud GNN often try to replicate research-paper architectures that assume unlimited inference time, running full multi-hop message passing synchronously in the authorization path. This blows the latency budget for card and payment authorization, and the project either gets scrapped or shipped only for offline investigation queues, missing the real-time prevention value that justified the graph investment in the first place.
What worked
Precomputing graph embeddings on a rolling batch schedule, refreshed every few minutes for high-activity accounts, and serving those embeddings through a low-latency feature store at authorization time, let teams get graph-level fraud signal into the real-time decision without running graph traversal synchronously, closing most of the gap between research accuracy and production latency constraints.
- Graph construction biasWhich edges you choose to build determines which fraud patterns are even detectable, independent of model architecture quality.
- Over-smoothing at depthStacking too many message-passing layers blurs node representations and can erase the exact local signal a fraud ring detector needs.
- Label leakage from rules enginesTraining naively on labels sourced from an existing rules system teaches the model to reproduce those rules rather than find new patterns.
- Embedding stalenessPrecomputed embeddings drift as account behavior changes, so refresh cadence is a direct lever on detection lag.
- Explainability for investigatorsA flagged account with no human-readable justification slows investigation teams and increases false-positive fatigue.
- Cross-institution data limitsFraud rings often span multiple institutions, but privacy and competitive constraints usually block building one shared graph across them.
- Retraining cadenceBecause fraudsters adapt to deployed detectors, a fixed retraining schedule quietly becomes a fixed exploitation window.
- Class imbalance handlingStandard oversampling techniques do not transfer cleanly to graph data, since duplicating a fraud node can distort the very neighborhood structure the model relies on.
- Message passing
- The core GNN mechanism where each node updates its representation by aggregating information from its connected neighbors, repeated over multiple layers.
- GraphSAGE
- An inductive graph neural network architecture that learns aggregation functions rather than fixed node embeddings, allowing it to generalize to nodes not seen during training.
- Temporal graph network
- A GNN variant that incorporates edge timestamps directly into message passing, capturing when interactions occurred rather than treating all historical edges equally.
- Structuring
- A money-laundering technique of splitting a large transfer into many smaller transactions specifically to stay under regulatory reporting or detection thresholds.
- Label scarcity
- The condition where confirmed fraud labels cover a very small, delayed, and biased fraction of transaction volume, limiting purely supervised training approaches.
- Heterogeneous graph
- A graph containing more than one type of node (such as accounts, devices, and merchants) and more than one type of edge, common in financial-crime graphs.
Key Takeaways
- Graph neural networks change the unit of fraud analysis from a single transaction to a connected neighborhood of accounts, devices, and transfers.
- Graph construction choices, which node and edge types to include, determine detection ceiling more than architecture selection does.
- GraphSAGE’s inductive design, generalizing to accounts never seen during training, is a non-negotiable requirement for production fraud graphs.
- Temporal graph networks like LAS-GNN and Amatriciana capture laundering patterns that unfold over time windows, not single snapshots.
- Label scarcity, delay, and bias toward existing rules engines are the deepest structural challenge, addressed with multi-task and semi-supervised methods.
- Fraud rings actively adapt to deployed detectors, so model performance decays without a deliberate, ongoing retraining cadence.
- Real-time authorization latency forces a split architecture: precomputed graph embeddings served fast, full graph inference reserved for investigation queues.
FAQs
How is a fraud GNN different from a standard fraud classifier?
A standard classifier scores one transaction using its own features. A GNN scores a transaction or account using information propagated from connected accounts, devices, and transfers, which lets it surface coordinated rings a per-transaction model cannot see.
Why is GraphSAGE preferred over transductive GNN architectures for fraud detection?
GraphSAGE learns aggregation functions instead of fixed embeddings for specific nodes, so it can generate a usable representation for a brand-new account immediately, without retraining, which matters because financial graphs constantly add new accounts.
What makes financial transaction graphs harder to work with than typical GNN benchmark graphs?
They are heterogeneous, containing multiple node types like accounts, devices, and merchants, and multiple edge types like transfers and shared-device links, and they evolve continuously in real time, unlike static citation or molecule graphs used in most tutorials.
How do temporal graph networks improve money-laundering detection?
They incorporate edge timestamps directly into message passing, letting the model learn time-sensitive patterns such as bursts of small transfers within a short window, which static graph snapshots would treat as unremarkable individually.
Why is label scarcity such a central problem in fraud GNN training?
Confirmed fraud labels are rare, arrive months after the fact, and are biased toward whatever an existing rules engine already flagged, so naive supervised training risks reproducing old rules rather than discovering new fraud patterns.
How do fraud rings adapt to deployed detection models?
Once a detection pattern proves reliable, rings restructure by spacing transfers differently, rotating intermediary accounts, or maintaining low-connectivity accounts that avoid accumulating detectable graph signal, requiring continuous retraining rather than a train-once approach.
How do production systems meet real-time latency requirements with graph models?
Most systems precompute graph embeddings offline or in near-real-time batches and serve them through a fast feature store at authorization time, reserving full synchronous graph traversal for post-transaction investigation rather than the authorization decision itself.
Can a single graph model cover fraud rings that span multiple financial institutions?
Rarely in practice, because privacy rules and competitive constraints usually prevent institutions from pooling transaction data into one shared graph, which is why cross-institution fraud rings remain one of the hardest patterns to detect with current GNN approaches.
Readers new to how these graphs are constructed and message-passing works at a fundamental level may also want the broader architectural grounding in model monitoring in production for keeping a deployed fraud GNN’s performance visible over time, and in privacy-preserving machine learning for the cross-institution data constraints described above. Building the labeling pipeline that feeds a fraud graph is closely related to the practices in data labelling in the age of synthetic data, while prioritizing which accounts need human investigation connects directly to active learning. Teams weighing federated or encrypted approaches to the cross-institution problem should also read zero-knowledge machine learning.
- Graph Neural Networks for Financial Fraud Detection: A Review, arXiv:2411.05815
- Transaction Fraud Detection via an Adaptive Graph Neural Network, arXiv:2307.05633
- Graph-Based Financial Fraud Detection with Calibrated Risk Scoring and Structural Regularization, arXiv:2605.12782
- Transaction Fraud Detection via Spatial-Temporal-Aware Graph Transformer, arXiv:2307.05121
- LAS-GNN: A Graph Neural Network for Temporal Money Laundering Motif Detection, ACM International Conference on AI in Finance
- Amatriciana: Exploiting Temporal GNNs for Robust and Efficient Money Laundering Detection, arXiv:2506.00654
- DELATOR: Money Laundering Detection via Multi-Task Learning on Large Transaction Graphs, arXiv:2205.10293
- Graph Neural Networks for Multi-Layered Financial Crime Network Detection: An Explainable AI Framework for Anti-Money Laundering, Journal of Engineering Research and Reports
- safe-graph/graph-fraud-detection-papers curated list, GitHub