| Defense Layer | What It Stops | What It Does Not Stop Alone |
|---|---|---|
| Input/output sanitization | Known malicious patterns, obvious encoded payloads | Novel phrasing, semantically disguised instructions |
| Content provenance tagging | Model confusing untrusted data for trusted instructions | An agent that ignores tags under adversarial pressure |
| Privilege separation (plan/execute) | A hijacked planner directly triggering high-impact actions | Damage within the execution layer’s own granted scope |
| Sandboxed tool execution | Compromised actions escaping their intended blast radius | Data already legitimately visible inside the sandbox |
Why Indirect Injection Requires Architectural Defense
Indirect prompt injection differs from most software vulnerabilities in a way that changes how it must be defended: the attacker never touches your system directly. Instead, they plant an instruction inside content your own agent will voluntarily retrieve, whether that is a web page, a document, an email, or a tool’s API response, and wait for your agent to process it as part of its normal, authorized job. There is no login to block, no exploit to patch, no malformed packet to reject. The attack succeeds by exploiting the fact that a large language model has no reliable way to distinguish “text I was told to analyze” from “instructions I was told to obey,” and both arrive in the same context window through the same channel.
This piece assumes you already understand that distinction; if you need the conceptual grounding first, our companion explainer on prompt injection’s direct, indirect, and multi-agent variants (linked in the references below) covers the taxonomy in depth. Here, the focus is exclusively on what to build: the four defense layers that, combined, meaningfully reduce both the likelihood and the blast radius of a successful indirect injection in a production agent workflow.
Layer One: Input and Output Sanitization
Sanitization is the first and least sufficient line of defense, but it remains a necessary baseline. On the input side, this means scanning any content an agent is about to ingest, whether from a web fetch, a document parser, or a tool response, for known injection patterns: instruction-like phrasing embedded in unexpected places, suspicious formatting designed to be invisible to a human reviewer (zero-width characters, off-screen text, metadata fields), and encoded payloads (Base64 blocks, homoglyphs, unusual Unicode) that would not normally appear in the expected content type.
On the output side, sanitization means never trusting an agent’s generated text or generated tool call to be safe by default. If an agent’s output is going to be executed as a command, inserted into a database query, or rendered as HTML, it must pass through the same validation any external, untrusted user input would face in a traditional web application. Microsoft’s guidance on defending against indirect prompt injection attacks explicitly frames this as treating retrieved content the same way a security team would treat any other untrusted external input: assume it can be adversarial until proven otherwise.
Practical sanitization techniques
- Pattern and heuristic scanning: flag content containing imperative phrasing (“ignore,” “disregard,” “you must now”), unusual encodings, or invisible formatting before it reaches the model’s context.
- Schema-constrained output: force tool calls and structured outputs through a strict schema validator so a model cannot smuggle an unexpected action inside a field that looks superficially valid.
- Semantic classifiers: run a lightweight, separate classifier model over both input and output specifically trained to detect injection-style content, rather than relying solely on static keyword lists.
- Rate and structure anomaly detection: flag content whose structure deviates sharply from what a given source normally produces, since injected instructions often distort the expected shape of a document or response.
Sanitization alone consistently fails against sufficiently motivated attackers because natural language allows near-infinite paraphrasing. This is why sanitization functions as a filter that reduces volume, not a wall that stops determined attacks, and why the remaining three layers exist.
Layer Two: Content Provenance Tagging
Content provenance tagging, sometimes called spotlighting, addresses the structural root of the problem directly: it marks every piece of content entering the model’s context with metadata about where it came from, so the model (and the surrounding application logic) can treat “developer instructions” and “retrieved external content” as distinguishable categories rather than an undifferentiated blob of text.
In practice, this means wrapping retrieved content in clear, consistent delimiters and explicitly instructing the model, at the system level, that anything inside those delimiters is data to be analyzed, summarized, or referenced, never a command to be obeyed regardless of its phrasing. Some architectures go further with a dual-model approach: a privileged model that only ever sees trusted developer instructions and orchestrates the overall task, and a quarantined model that processes untrusted retrieved content in isolation and can only return structured, validated data back to the privileged model, never free-form instructions.
Provenance Tagging in a Web-Browsing Agent
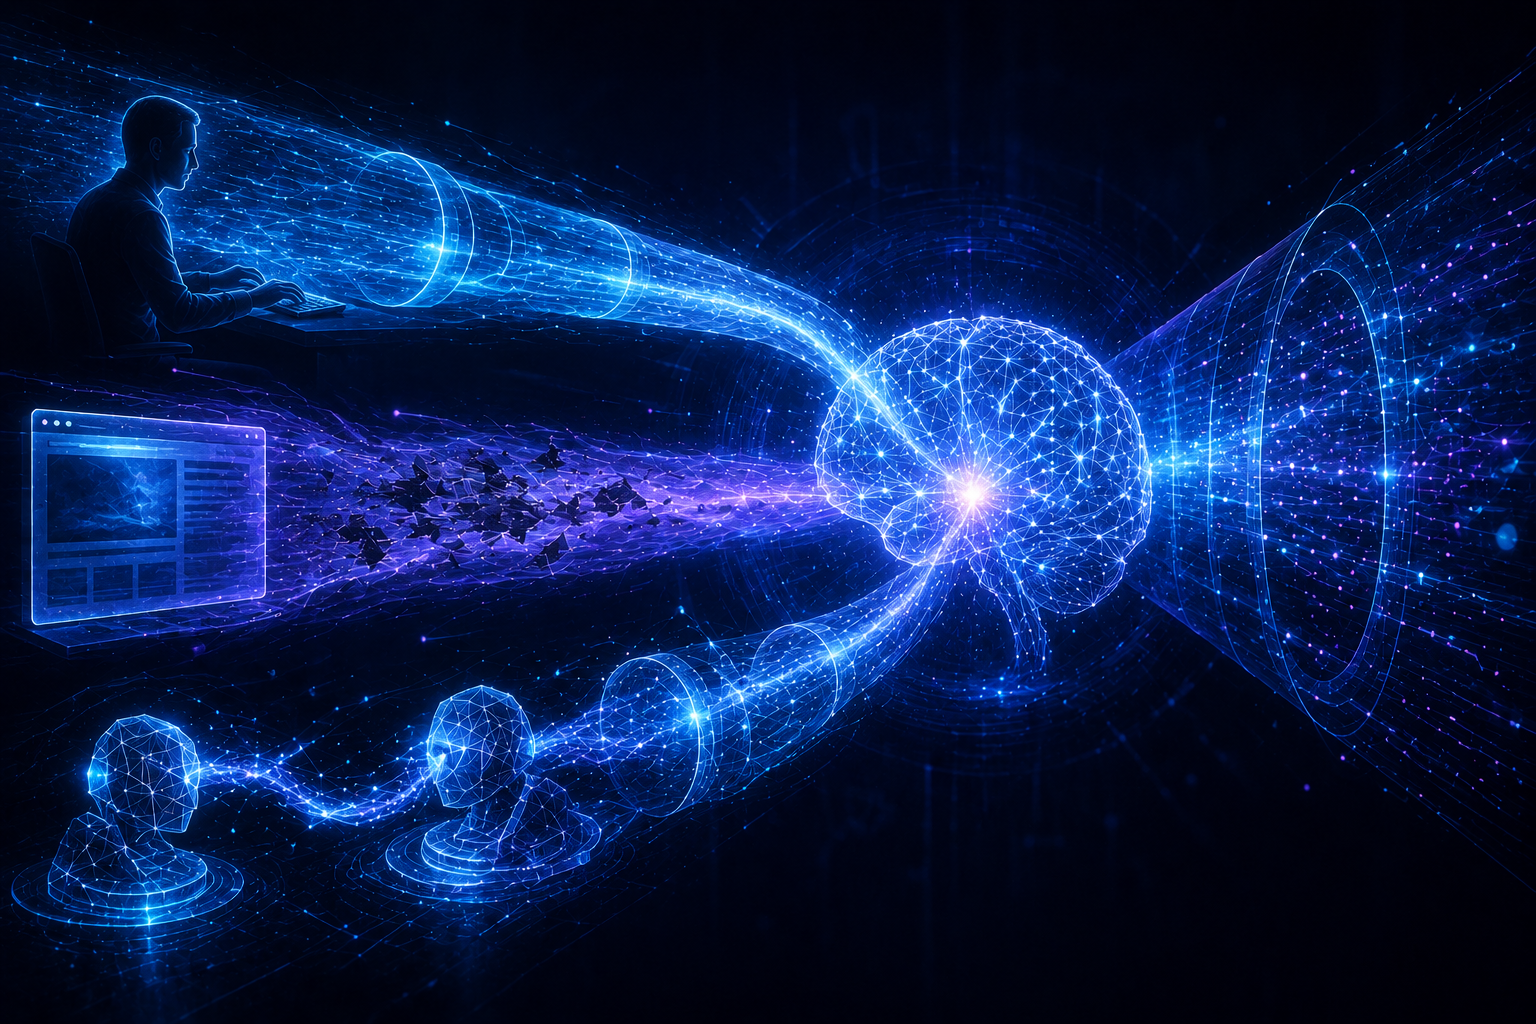
A privileged planner model holds the user’s original request and the developer’s system instructions. When it needs to read a web page, it delegates that specific sub-task to a quarantined model that only ever sees the tagged, untrusted page content. The quarantined model can return a structured summary field back to the planner, but it cannot issue new instructions or trigger tool calls, closing the path an injected instruction would need to reach the privileged execution layer.
Provenance tagging is not foolproof; a sufficiently adversarial instruction can still attempt to convince the model that it is, in fact, a legitimate developer instruction despite the tagging. This is why tagging is paired with privilege separation rather than relied upon in isolation.
Layer Three: Privilege Separation Between Planning and Execution
This is the architectural control with the highest leverage against indirect injection, and the one most production agent systems still lack. The core idea, drawn from research on type-directed privilege separation and structural defenses like agent privilege separation frameworks, is to split an agent’s cognitive planning from its ability to act. A planning layer reasons about what should happen next and can read untrusted content freely, since reading alone cannot cause external harm. An execution layer holds the actual credentials and permissions to call tools, write to databases, send emails, or move money, and it only accepts a narrow, validated, structured instruction from the planning layer, never raw natural language influenced by untrusted content.
Concretely, this means the planning layer might decide “the user wants their inbox summarized,” but the execution layer, before actually calling the email API, independently validates that the requested action (read-only summary, in this example) matches what the user’s original, trusted request actually authorized. If a hidden instruction inside an email convinced the planning layer to attempt to forward five emails to an external address, the execution layer’s independent validation against the user’s original authorized scope would reject an action the user never requested, regardless of what the planning layer now believes it should do.
Designing the plan/execute boundary
- Structured handoff only: the planning layer can never pass free-form natural language directly to a tool; it must produce a validated, typed action request.
- Independent authorization check: the execution layer re-verifies every action against the user’s original, trusted request, not against whatever the planning layer currently claims the user wants.
- Least privilege by task: the execution layer’s available permissions should be scoped per task, not held as a standing broad grant, so even a successful bypass of the planning layer has a small blast radius.
- Explicit escalation gates: any action outside the narrow, pre-authorized scope (sending money, deleting data, contacting a new external party) requires a separate, harder-to-forge confirmation, ideally a human approval step.
Layer Four: Sandboxed Tool Execution
Even with strong privilege separation, the execution layer still needs to actually run something, whether that is a code interpreter, a browser automation step, or a file operation. Sandboxing ensures that whatever runs, runs inside a contained environment where the worst-case outcome of a successful injection is limited to that sandbox, not the broader production environment.
Isolation technology choices range along a spectrum. Firecracker microVMs and similarly strong virtualization offer the highest isolation guarantees, appropriate for agents that execute arbitrary generated code. gVisor and similar user-space kernel interception approaches offer a lighter-weight middle ground suitable for many containerized agent workloads. WebAssembly-based sandboxes work well for isolating third-party plugins with a defined, narrow capability surface. The right choice depends on what the agent’s tools actually need to do, but the underlying principle is constant: assume any single tool call could be attacker-influenced, and design the blast radius accordingly.
| Sandboxing Approach | Isolation Strength | Best Fit |
|---|---|---|
| Firecracker microVMs | Very high (hardware-level virtualization) | Agents executing arbitrary generated code |
| gVisor / user-space kernel interception | High | General containerized agent tool execution |
| Hardened containers | Moderate | Well-understood, narrow-scope tool workloads |
| WebAssembly sandboxes | Moderate to high, narrow capability surface | Third-party plugin isolation |
Putting the Four Layers Together
None of these four layers is sufficient in isolation, and that is by design. Sanitization catches the volume of unsophisticated attempts before they cost engineering effort further down the pipeline. Provenance tagging reduces the odds that content which slips past sanitization is misread as an instruction. Privilege separation ensures that even a successful misread cannot translate directly into a high-impact action. Sandboxed execution ensures that even a successful, authorized-looking action is contained to a limited blast radius. A team that implements only one of these layers, most commonly sanitization because it is the easiest to bolt onto an existing system, will find that layer alone catches perhaps the most obvious attacks in a red-team exercise and little else.
The order of implementation matters for teams with limited engineering budget. Privilege separation between planning and execution delivers the largest single reduction in worst-case impact, because it constrains what a successful injection can actually accomplish regardless of how it got in. Sandboxed execution is the natural second priority, since it contains whatever privilege separation does not fully prevent. Provenance tagging and sanitization are valuable but should be understood as raising the cost of an attack, not eliminating it.
Frequently Overlooked Implementation Details
- Tool output re-taggingTeams tag content when it first enters the system but forget that a tool’s own output, derived from that tagged content, needs to inherit the same untrusted status rather than being treated as newly trustworthy.
- Escalation-gate fatigueIf every action triggers a human approval prompt, operators start approving reflexively, which defeats the purpose; escalation gates should be reserved for genuinely high-impact actions outside the pre-authorized scope.
- Sandbox data leakageA sandbox that isolates execution but still grants read access to the same sensitive data the rest of the system uses provides much weaker protection than teams assume.
- Static provenance labelsProvenance tags applied once at ingestion can be stripped or lost as content is transformed and passed between processing steps, silently reverting to an untagged, ambiguous state.
- Execution-layer credential scopeExecution layers are frequently granted broader standing permissions than any single task requires, undermining the entire purpose of separating planning from execution in the first place.
Common mistake
Deploying a single input filter or classifier and treating indirect prompt injection as solved. This is the most common failure pattern in production agent deployments: a team runs a red-team exercise, the filter catches the obvious test cases, and the project moves on. Because indirect injection content is planted by attackers with time to iterate and no visibility constraints (they can test their payload against the same publicly available model your agent uses), a filter tuned against known test cases will miss novel phrasing within weeks. Defense requires the layered approach described above, not a single control declared sufficient after one testing pass.
What worked
Teams that meaningfully reduced their indirect injection exposure started with privilege separation, not sanitization. They identified every point where an agent’s output could trigger a real-world action, split that action authority into a separate execution layer with its own independent validation against the user’s original request, and only then layered sanitization and provenance tagging on top to reduce the volume of attempts reaching that boundary. Starting with architecture rather than filtering produced measurably smaller blast radii during subsequent red-team exercises.
Glossary
- Privilege separation
- An architectural pattern that splits an agent’s reasoning and planning capability from its ability to execute real-world actions, so a compromised planning layer cannot directly trigger high-impact operations.
- Content provenance tagging
- A technique that marks content entering a model’s context with metadata about its trust level or origin, helping distinguish developer instructions from untrusted retrieved data.
- Sandboxed tool execution
- Running an agent’s tool calls or generated code inside an isolated environment so that a compromised or malicious action is contained rather than able to affect the broader production system.
- Quarantined model
- A secondary model instance that processes untrusted external content in isolation and can only return structured, validated data to a privileged model, never free-form instructions.
- Blast radius
- The scope of damage a single security failure can cause, determined by how much access, data, or capability was reachable from the point of compromise.
- Escalation gate
- A checkpoint requiring explicit, harder-to-forge confirmation, often human approval, before an agent can take an action outside its narrow, pre-authorized scope.
Key Takeaways
- Indirect prompt injection cannot be solved by a single control because the attacker never touches the system directly, only the content it later retrieves.
- Input and output sanitization is a necessary but insufficient baseline that reduces volume rather than eliminating sophisticated attacks.
- Content provenance tagging helps separate trusted instructions from untrusted retrieved data, but a determined attacker can still attempt to spoof legitimacy within the tagged content itself.
- Privilege separation between an agent’s planning and execution layers delivers the largest single reduction in worst-case impact, since it constrains what a successful injection can actually accomplish.
- Sandboxed tool execution contains whatever privilege separation does not fully prevent, limiting a compromised action’s blast radius.
- The four layers are complementary, not redundant; teams that implement only sanitization consistently find gaps in subsequent red-team exercises.
- Prioritizing privilege separation and sandboxing before investing further in filtering and tagging produces the fastest reduction in real-world impact for limited engineering budgets.
FAQs
What is the single most effective defense against indirect prompt injection?
Privilege separation between an agent’s planning and execution layers delivers the largest reduction in worst-case impact, because it constrains what a successful injection can actually accomplish, independent of whether the injection was detected at all. No single control eliminates the risk entirely, but this one reduces impact the most.
Does input filtering alone stop indirect prompt injection?
No. Input filtering catches known attack patterns but fails against novel phrasing, since natural language allows near-infinite paraphrasing and encoding. It should be treated as a volume-reduction measure, not a complete defense, and paired with provenance tagging, privilege separation, and sandboxing.
What is content provenance tagging in the context of AI agents?
Content provenance tagging marks retrieved or external content with metadata indicating its untrusted origin, so the model and surrounding application logic can distinguish it from trusted developer instructions. It is often implemented through delimiters, dual-model architectures, or explicit system-level instructions about how to treat tagged content.
How does privilege separation differ from simple permission scoping?
Permission scoping limits what an agent can do overall. Privilege separation goes further by architecturally splitting the reasoning process (which can be influenced by untrusted content) from the execution process (which independently validates any action against the user’s original authorized request before acting).
What kind of sandboxing is appropriate for an agent that executes generated code?
Agents executing arbitrary generated code benefit most from strong virtualization approaches like Firecracker microVMs, which offer hardware-level isolation. Lighter-weight options like gVisor or hardened containers may be appropriate for agents with narrower, well-understood tool execution needs.
Can indirect prompt injection be completely eliminated?
Not with current architectures. The goal of the defenses described here is to reduce likelihood and, more importantly, reduce the impact of a successful injection, not to guarantee zero incidents. Continuous red-teaming and monitoring remain necessary even after implementing all four defense layers.
Why do escalation gates sometimes fail as a defense?
If escalation gates trigger too frequently, operators develop approval fatigue and begin approving requests reflexively without genuine review, defeating the purpose of the gate. Escalation gates work best when reserved for genuinely rare, high-impact actions outside an agent’s normal pre-authorized scope.
How should a team prioritize these four defense layers with limited engineering time?
Start with privilege separation between planning and execution, since it delivers the largest reduction in worst-case impact. Add sandboxed execution next to contain whatever privilege separation does not prevent. Layer content provenance tagging and input/output sanitization on top to reduce the volume of attempts reaching those architectural boundaries.
References
- Microsoft Learn, “Defend against indirect prompt injection attacks”
- Amazon Web Services, “Securing Amazon Bedrock Agents: A guide to safeguarding against indirect prompt injections”
- SentinelOne, “What is Indirect Prompt Injection? Risks and Prevention”
- arXiv, “AgentVisor: Defending LLM Agents Against Prompt Injection via Semantic Virtualization”
- arXiv, “Preventing Prompt Injection with Type-Directed Privilege Separation”
- arXiv, “Agent Privilege Separation in OpenClaw: A Structural Defense Against Prompt Injection”
- arXiv, “A Systematic Survey of Security Threats and Defenses in LLM-Based AI Agents: A Layered Attack Surface Framework”
Readers who need the conceptual taxonomy before diving into architecture should start with prompt injection explained: direct, indirect, and multi-agent variants. This defense strategy complements the broader OWASP Top 10 for LLM applications checklist, and pairs naturally with dedicated agent sandboxing architecture and red-teaming practices for AI systems covered elsewhere on this site. For the machine-identity side of scoping execution-layer credentials, see machine identity at scale.