A streaming data pipeline built on Kafka and Flink can deliver exactly-once processing by combining Kafka’s idempotent and transactional producer protocol with Flink’s checkpoint-based state snapshots and two-phase commit sinks. Each layer, source, processing, and sink, must independently guarantee exactly-once behavior for the whole pipeline to hold that guarantee end to end.
| Myth | Reality |
|---|---|
| Exactly-once means a message physically arrives only one time | It means the observable effect of processing is applied only once, even if the underlying message is delivered or reprocessed more than once |
| Kafka alone can guarantee exactly-once for an entire pipeline | Kafka’s transactional protocol covers producers and Kafka Streams, but a full pipeline also needs the processing layer and sink to cooperate |
| Enabling exactly-once always cuts throughput drastically | Documented Confluent and Apache benchmarks show the overhead is modest and shrinks with larger batch and linger settings |
| Flink’s checkpointing is the same thing as Kafka’s transactions | Checkpointing snapshots Flink’s internal operator state, while Kafka transactions make a set of writes to Kafka partitions atomic |
What Exactly-Once Semantics Actually Means
Every streaming data pipeline has to pick a delivery guarantee: at-most-once, at-least-once, or exactly-once. At-most-once risks silently dropping data. At-least-once risks duplicate processing, such as double-counting a payment. Exactly-once semantics aim for the middle ground where each event affects the final result precisely one time, even when retries, restarts, or network failures occur along the way.
The nuance most teams miss is that exactly-once is a property of the whole pipeline, not a single component. A streaming data pipeline that reads from Kafka, transforms events in Flink, and writes to a downstream store only achieves end-to-end exactly-once when every stage, ingestion, processing, and output, honors the same guarantee. This is closely related to the broader move toward big data analytics platforms that process events continuously rather than in overnight batches.
Kafka’s Building Blocks for Reliable Pipelines
Apache Kafka was originally built at LinkedIn to handle high-volume activity data and became an Apache Software Foundation top-level project soon after its release. It provides the durable, ordered log that most streaming pipelines rely on as their source of truth.
Partitions and Ordering
A Kafka topic is split into partitions, and Kafka guarantees ordering only within a single partition, not across an entire topic. Pipeline designers choose a partitioning key, often a customer or entity identifier, so that all events for the same entity land in the same partition and are processed in order.
Replication and Durability
Each partition is replicated across multiple brokers, with one broker acting as leader and the others as followers. Producers can require acknowledgment from all in-sync replicas using the acks=all setting, which trades a small amount of latency for much stronger durability guarantees against broker failure.
Idempotent Producers and Transactions
Kafka introduced its idempotent producer and transactional API through KIP-98, assigning each producer a unique producer ID and per-partition sequence numbers so brokers can detect and discard duplicate writes caused by retries. The transactional API extends this further, letting a producer write to multiple partitions atomically, which is the foundation Kafka Streams uses for its own exactly-once processing guarantee.
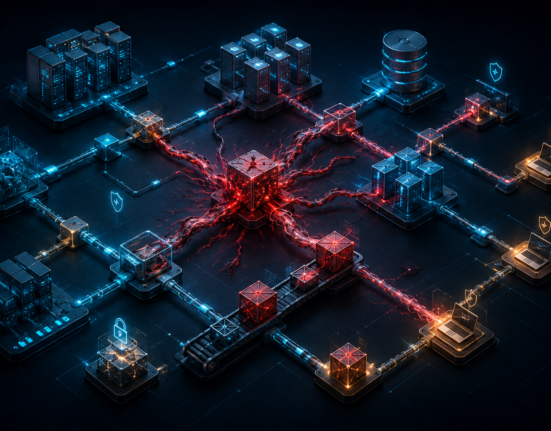
Figure 1: The Three Layers That Must Agree on Exactly-Once
Source layer (Kafka idempotent and transactional producers) then processing layer (Flink checkpointing and state snapshots) then sink layer (transactional or idempotent writes to the destination system).
If any one of these three layers only supports at-least-once delivery, the entire pipeline inherits that weaker guarantee.
Apache Flink’s Approach to Stateful Streaming
Apache Flink grew out of the Stratosphere research project and became an Apache Software Foundation top-level project in the mid-2010s. Unlike micro-batch engines, Flink processes events one at a time as a true streaming engine while still offering strong consistency guarantees for stateful computations.
Checkpointing and Barriers
Flink takes consistent, distributed snapshots of all operator state using a barrier-based algorithm inspired by the Chandy-Lamport distributed snapshot method. Checkpoint barriers flow through the data streams alongside regular records, and when an operator has seen a barrier from every input, it snapshots its state to durable storage.
State Backends
Flink stores operator state in a pluggable state backend, commonly RocksDB for large state that exceeds available memory, with periodic checkpoints copied to durable storage such as an object store or distributed file system. This lets a failed job restart from the most recent checkpoint rather than reprocessing from the beginning of the stream.
Two-Phase Commit Sinks
To extend exactly-once guarantees all the way to external systems, Flink uses a two-phase commit pattern in its sink connectors. The Kafka sink, for example, opens a Kafka transaction, writes records during normal processing, and only commits the transaction once a checkpoint confirming that data has completed successfully, aligning Flink’s internal snapshot with Kafka’s transactional commit.
Kafka Plus Flink: The End-to-End Exactly-Once Pipeline
When Kafka’s transactional producer feeds a Flink job, and that Flink job writes back to Kafka (or another transactional sink) using a two-phase commit sink, the pipeline achieves end-to-end exactly-once processing. Flink’s checkpoint completion is the trigger that commits the corresponding Kafka transaction, so a failure between checkpoints results in a clean replay rather than a duplicate or lost write. Teams building this pattern often pair it with the backend re-architecture patterns already reshaping how services are built around continuous data rather than periodic batch jobs. Once events are processed and deduplicated, many teams serve the resulting aggregates through a dedicated serving layer; our comparison of ClickHouse, Druid, and Pinot for real-time analytics covers how that final serving layer is typically chosen.
| Guarantee | What It Covers | How Kafka Plus Flink Achieves It |
|---|---|---|
| At-most-once | No duplicates, but data loss is possible | Fire-and-forget producer, no retries, no checkpoint recovery |
| At-least-once | No data loss, but duplicates are possible | Producer retries plus consumer offset commits after processing |
| Exactly-once | No data loss and no duplicate effects | Idempotent and transactional Kafka producers combined with Flink checkpointing and two-phase commit sinks |
Tuning for Throughput Without Breaking Guarantees
Batch and Linger Settings
Kafka producers batch records together before sending, controlled by the batch.size and linger.ms settings. Larger batches amortize the per-message overhead that Kafka’s transactional protocol adds, which is why documented Confluent benchmarks describe the throughput cost of exactly-once semantics as modest rather than severe once batching is tuned appropriately for the workload.
Checkpoint Interval Trade-offs
Flink’s checkpoint interval controls how much work must be replayed after a failure. A shorter interval reduces reprocessing time but increases checkpointing overhead, while a longer interval reduces overhead but increases the amount of in-flight data that must be replayed. Flink’s own documentation recommends tuning this interval against the state size and the acceptable recovery time for each specific job.
Figure 2: Checkpoint Interval Trade-off
Short checkpoint interval: lower replay cost after failure, higher steady-state overhead. Long checkpoint interval: lower steady-state overhead, higher replay cost after failure.
Most production Flink jobs settle somewhere between several seconds and a few minutes, depending on state size and how expensive replay would be.
Common Mistakes When Building Streaming Pipelines
Mistake
Assuming that enabling exactly-once semantics in Kafka Streams or a Flink job automatically covers every downstream system, when the sink itself also needs idempotent or transactional writes.
Mistake
Choosing a partitioning key that does not match the entity that needs ordering guarantees, which breaks per-key ordering even though Kafka’s partition-level ordering is intact.
Mistake
Setting checkpoint intervals without testing recovery time under realistic state sizes, leading to unpleasant surprises the first time a job actually fails in production.
Mistake
Treating acks=all as sufficient on its own, without also configuring min.insync.replicas, which leaves a gap between the intended and actual durability guarantee.
Mistake
Scaling consumer instances past the number of partitions in a topic, which leaves some consumers permanently idle since Kafka cannot assign more consumers than partitions within a group.
How Expert Teams Build These Pipelines
Practice
Experienced teams size partition counts for peak expected parallelism up front, since increasing partitions later can disrupt existing key-to-partition ordering assumptions.
Practice
Production Flink deployments typically externalize checkpoints to durable object storage and test full recovery drills before a pipeline goes live, not after an incident.
Practice
Mature platform teams monitor consumer lag and checkpoint duration as primary health signals, treating a growing gap between the two as an early warning of capacity problems. Teams building fully automated response systems often extend these guarantees into event-driven operational workflows that act on validated events without manual intervention.
Practice
Teams that need durable, replayable event history alongside their streaming layer frequently connect the pipeline to a broader cloud data platform rather than treating Kafka retention as permanent storage.
Glossary
- Exactly-once semantics
- A delivery guarantee ensuring each event affects the final result precisely one time, even across retries or failures.
- Idempotent producer
- A Kafka producer configuration that assigns sequence numbers to messages so brokers can detect and discard duplicate writes from retries.
- Transactional API
- A Kafka feature that lets a producer write to multiple partitions as a single atomic unit, committed or aborted together.
- Checkpoint
- A consistent, distributed snapshot of a Flink job’s operator state, used to recover processing after a failure.
- Two-phase commit sink
- A sink pattern that opens a transaction, writes data, and commits only after a checkpoint confirms the data is safe to make visible.
- Consumer lag
- The gap between the latest message written to a Kafka partition and the last message a consumer group has processed.
- State backend
- The storage mechanism Flink uses to hold operator state, such as an in-memory store or RocksDB for larger state.
Key Takeaways
- Exactly-once semantics is a property of the whole pipeline, not any single component in isolation.
- Kafka’s idempotent producer and transactional API, introduced through KIP-98, form the foundation for exactly-once writes at the source.
- Flink achieves consistency through barrier-based checkpointing inspired by the Chandy-Lamport distributed snapshot algorithm.
- Two-phase commit sinks align Flink’s checkpoint completion with Kafka’s transaction commit to close the loop end to end.
- Partitioning strategy determines ordering guarantees, since Kafka only guarantees order within a single partition.
- Checkpoint interval is a direct trade-off between steady-state overhead and replay time after a failure.
- Documented benchmarks show exactly-once overhead is modest once batch and linger settings are tuned for the workload.
FAQs
What is the difference between at-least-once and exactly-once delivery?
At-least-once guarantees no data loss but allows the same event to be processed more than once, which can cause duplicate side effects. Exactly-once adds deduplication and atomic commit mechanisms so each event affects the final result only a single time, even after retries or failures.
Does Kafka guarantee ordering across an entire topic?
No. Kafka only guarantees ordering within a single partition. Events assigned to different partitions can be processed in any relative order, which is why the choice of partitioning key matters so much for pipelines that depend on strict per-entity ordering.
How does Flink recover from a failure without losing data?
Flink periodically snapshots the state of every operator in a job to durable storage through its checkpointing mechanism. When a failure occurs, the job restarts from the most recent completed checkpoint and replays only the data received since that checkpoint, rather than reprocessing the entire stream.
What is a two-phase commit sink in Flink?
It is a sink pattern where a connector opens a transaction, writes records during normal processing, and only commits that transaction once Flink confirms the corresponding checkpoint completed successfully. This keeps the sink’s committed data aligned with Flink’s internal state snapshots.
Does enabling exactly-once semantics significantly slow down Kafka?
Documented benchmarks from the Kafka project and Confluent’s engineering team describe the overhead as modest, mainly a small amount of extra metadata per message and per-partition transactional coordination. Tuning batch size and linger settings reduces the relative impact considerably compared with default configurations.
Can exactly-once semantics work with sinks other than Kafka?
Yes, as long as the destination system supports transactional or idempotent writes. Flink ships connectors implementing two-phase commit for several transactional stores, and for non-transactional sinks teams often achieve equivalent guarantees using idempotent writes keyed on a unique event identifier.
Why do some teams choose at-least-once instead of exactly-once?
Exactly-once introduces coordination overhead and operational complexity that is not always worth it. If downstream processing is naturally idempotent, such as an upsert keyed by ID, at-least-once delivery combined with idempotent writes can reach the same practical outcome with less machinery.
How should a team validate that its pipeline truly achieves exactly-once?
Test failure scenarios directly rather than trusting configuration alone. Kill brokers and task managers mid-processing, restart consumers from committed offsets, and verify downstream record counts and checksums match expectations under repeated, deliberately induced failure conditions before trusting the guarantee in production.
References
- Apache Kafka Documentation, “Kafka Design and Implementation,” kafka.apache.org/documentation
- Apache Kafka KIP-98, “Exactly Once Delivery and Transactional Messaging,” cwiki.apache.org
- Confluent Engineering Blog, “Exactly-Once Semantics in Apache Kafka,” confluent.io/blog
- Apache Flink Documentation, “Checkpointing,” nightlies.apache.org/flink/flink-docs-stable
- Apache Flink Documentation, “Fault Tolerance via State Snapshots,” nightlies.apache.org/flink/flink-docs-stable
- Apache Flink Documentation, “Kafka Sink and Exactly-Once Delivery,” nightlies.apache.org/flink/flink-docs-stable
- Confluent Engineering Blog, “Building Reliable Streaming Data Pipelines,” confluent.io/blog