| Assumption | What research actually shows |
|---|---|
| An API-only deployment protects the underlying model weights. | Model extraction reconstructs a functional copy of a model purely from its input-output behavior, with no access to weights or infrastructure required. |
| Basic rate limiting stops extraction attempts. | Distillation attacks can capture specialized model logic and domain behavior efficiently even when the target is protected by basic per-account rate limits, especially when attackers distribute queries across many accounts. |
| Extraction requires the same scale of compute as the original training run. | An extraction attack can replicate much of a model’s value for a fraction of its original cost, often just the price of API query fees. |
| Watermarking alone proves theft in court. | Watermarking supports an ownership claim but works best paired with API-level monitoring and rate controls that prevent extraction before it completes. |
What Model Extraction Actually Is
Model extraction, sometimes called model stealing, is an attack in which an adversary reconstructs a functional copy of a proprietary machine learning model by systematically querying its public-facing API and using the resulting input-output pairs to train a separate “shadow” model that mimics the original’s behavior. The foundational research establishing this threat dates to Florian Tramer and colleagues’ 2016 paper presented at the USENIX Security Symposium, which demonstrated that decision boundaries of models including support vector machines and neural networks could be extracted with a surprisingly small number of queries. Nearly a decade later, the technique has matured into a serious commercial threat against large language models and other API-served systems, where training a frontier model can cost tens of millions of dollars in compute alone, plus years of research, proprietary training data, and specialized alignment work that an extraction attack can partially replicate for the cost of API access fees.
The stakes have risen alongside the growth of the AI-as-a-service business model. When a company’s entire competitive advantage is embodied in a model served exclusively through an API, model extraction represents a direct threat to that business model, not merely a theoretical academic exercise. Security researchers at firms including Praetorian have published practical demonstrations of model extraction attacks against production-style API deployments, showing the techniques scale beyond laboratory conditions.
What makes model extraction especially difficult to budget for is that it rarely announces itself. Unlike a data breach involving credential theft or a ransomware event, a successful extraction campaign leaves no obvious operational disruption; the original model keeps serving requests normally while a competitor or unauthorized party quietly builds a functional replica in the background, often discovered only when a suspiciously similar product appears in the market months later.
| Extraction technique | Mechanism | What it targets |
|---|---|---|
| Query-based extraction | Repeated systematic queries capture output behavior across the input space, used to train a replica model | General model behavior and decision boundaries |
| Distillation-based extraction | Using the target model’s outputs as training labels for a smaller student model | Specialized domain logic and task-specific behavior |
| Membership and boundary probing | Crafted queries near decision boundaries to map them precisely with fewer total queries | Model architecture and decision-boundary shape |
| Reverse engineering via outputs | Analyzing output patterns, confidence scores, and error behavior to infer architecture or training data characteristics | Underlying model design and training methodology |
| Insider and supply-chain exfiltration | Direct theft via compromised employees, contractors, or vendor access rather than querying alone | Actual model weights and training artifacts |
Why Rate Limiting Alone Is Not Enough
Rate limiting restricts query volume per account or API key to prevent the bulk data collection an extraction attack requires, and it remains a necessary first layer of defense. However, rate limiting alone is insufficient because coordinated extraction campaigns distribute queries across many accounts, API keys, or IP addresses to stay below any single per-account threshold, effectively parallelizing the attack across enough distinct identities that no individual account triggers an alert. Distillation attacks compound this problem further: because they can capture specialized logic and domain behavior efficiently, an attacker does not need to query the full breadth of a model’s capability space, only the specific subset relevant to the domain they intend to replicate, meaning even a well-tuned rate limit calibrated for broad extraction can miss a narrower, faster distillation attempt.
The Query-to-Shadow-Model Pipeline
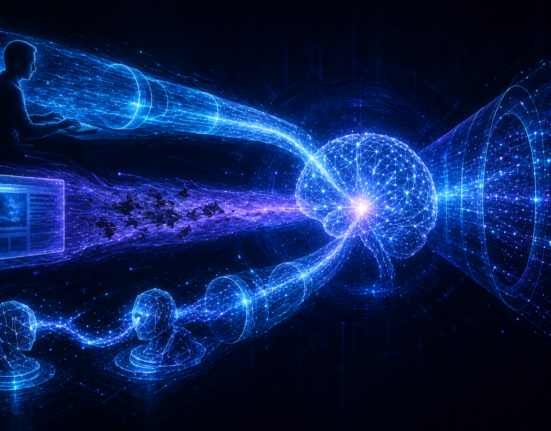
A four-stage diagram showing an attacker issuing a large volume of systematic queries against a target model’s API, capturing the resulting input-output pairs into a labeled dataset, training a smaller shadow or student model on that captured dataset using distillation, and deploying the resulting shadow model as a low-cost functional replica of the original, illustrating how the entire chain never requires access to the original model’s weights or infrastructure.
Building Layered API Defenses
Aggressive, risk-weighted rate limiting
Effective rate limiting goes beyond flat per-key thresholds, weighting limits by account age, verification level, and behavioral risk signals, applying the tightest limits to new or unverified accounts where extraction campaigns are most likely to originate.
API query monitoring for extraction-pattern behavior
Beyond volume alone, monitoring should flag systematic coverage patterns, such as queries that methodically sweep the input space, unusually high query diversity relative to typical usage, or distribution patterns inconsistent with genuine application traffic, all signals that distinguish an extraction campaign from normal usage even when volume per account stays low.
Output perturbation and controlled noise
Introducing small amounts of controlled noise into model outputs, particularly confidence scores and probability distributions, can degrade the quality of a shadow model trained on those outputs without meaningfully harming the experience of a legitimate user relying on the primary output.
Watermarking and fingerprinting
Model watermarking aims to implant a triggerable, detectable pattern into model behavior that transfers into any model trained on its outputs, allowing an owner to later assert ownership by testing a suspected copy for the watermark’s presence. Recent research including performance-lossless black-box watermarking, knowledge-injection watermarking, and frameworks such as Neural Honeytrace and ModelShield represent an active and rapidly evolving research area specifically targeting extraction-resistant watermark survivability.
| Defense layer | What it addresses | Key limitation |
|---|---|---|
| Risk-weighted rate limiting | Bulk query volume from a single account or key | Bypassed by distributing queries across many accounts |
| Extraction-pattern query monitoring | Systematic input-space coverage regardless of per-account volume | Requires baseline of normal usage patterns to detect deviation |
| Output perturbation | Shadow-model training quality when outputs are used as training labels | Must balance noise level against legitimate user experience |
| Watermarking and fingerprinting | Post-hoc proof of ownership if a stolen copy surfaces | Does not prevent extraction itself, only supports later claims |
| Vendor and contract controls | Insider and supply-chain exfiltration of actual weights | Ineffective against pure query-based extraction from outside the organization |
Legal and Contractual Dimensions
Technical controls address the mechanics of extraction, but organizations serious about protecting proprietary weights also need the legal and contractual scaffolding to act once theft is suspected. Terms of service for API access typically prohibit systematic querying intended to reverse-engineer or replicate model behavior, giving a provider contractual grounds to suspend an account and pursue damages even before any watermark evidence is available, though enforcement in practice usually depends on being able to demonstrate the pattern of abuse through logged query behavior.
Watermarking evidence becomes most valuable at this legal stage, since a triggerable pattern detected in a competitor’s product provides a concrete, technical basis for an ownership claim that is far stronger than circumstantial similarity in output style or capability alone. Organizations pursuing this path should establish a watermarking approach before deployment, since retrofitting a watermark into an already-deployed model is far more constrained than designing it in from the outset.
Vendor and partner contracts deserve equal scrutiny, since organizations frequently grant elevated API access to integration partners, resellers, or enterprise customers under commercial agreements that may not carry the same extraction-specific restrictions as public-facing terms of service. A comprehensive model-protection program should audit these commercial relationships for gaps just as carefully as it audits public API rate limits, since a well-intentioned partner’s compromised credentials can become an extraction vector indistinguishable, from a technical monitoring standpoint, from a malicious actor operating under the same access tier.
Enterprise Governance Beyond the API
Technical API defenses address only one extraction vector. Enterprises reduce overall model-theft risk with layered controls spanning identity, API access, code repositories, runtime monitoring, watermarking, vendor governance, and compliance, recognizing that a determined attacker with insider access or supply-chain leverage can bypass API-level protections entirely. Identity and access controls deserve particular attention as AI systems increasingly involve service accounts and automated agents querying models on behalf of applications, a theme explored further in our analysis of machine identity at scale, since a compromised service credential can provide an attacker with elevated query privileges that bypass consumer-tier rate limits entirely.
Organizations serving models through agentic platforms should also consider how sandboxing affects extraction risk, since an agent with broad tool access may inadvertently expose more of a model’s behavior than a narrowly scoped API endpoint would, a consideration covered in our piece on agent sandboxing. Regularly red-teaming a deployed API specifically for extraction susceptibility, rather than only for prompt injection or jailbreak resistance, is increasingly considered a baseline practice, discussed in our broader guide to red-teaming AI systems. Organizations running multiple models across different business units often discover during this exercise that extraction-specific controls were implemented inconsistently, with a flagship consumer-facing model receiving significant protection while an internal or partner-facing model with equally valuable fine-tuned behavior was left with only default rate limits.
Building a Defense Program: A Practical Sequence
- Classify which models carry extraction risk. Prioritize models representing genuine competitive advantage or significant training investment over commodity or open-weight deployments.
- Implement risk-weighted rate limiting. Apply tighter limits to new, unverified, or unusually active accounts rather than a single flat threshold for all traffic.
- Deploy extraction-pattern monitoring. Instrument logging and anomaly detection specifically tuned to systematic query coverage and distribution patterns, not just raw volume.
- Add output perturbation where feasible. Introduce controlled noise into confidence scores and probability outputs without degrading the primary response quality.
- Implement watermarking for high-value models. Adopt a watermarking approach appropriate to the model type to support future ownership claims if a stolen copy surfaces.
- Red-team the API for extraction susceptibility. Run internal extraction attempts against production APIs to validate that monitoring and rate limits would actually catch a real attack.
Common mistake
Treating a single flat rate limit as sufficient protection against model extraction. Coordinated campaigns distribute queries across many accounts specifically to stay under any single threshold, meaning a defense that only monitors per-account volume will miss a well-organized distributed extraction attempt entirely, regardless of how strict that single-account limit is set.
What worked
An API provider serving a fine-tuned domain-specific model identified a distillation-style extraction attempt not through volume alerts but through query-diversity monitoring, which flagged an account whose queries systematically swept edge cases and rare input patterns far outside the distribution of genuine application traffic, prompting a manual review that confirmed the extraction attempt before it captured enough data to produce a usable shadow model. The provider subsequently added query-diversity scoring as a standing detection layer across all its API tiers, not just the flagship product that had originally prompted the investigation.
Frequently Overlooked Elements of Model-Theft Defense
- Distributed account campaignsSecurity teams often tune rate limits against a single-account threat model, missing that real extraction campaigns increasingly spread queries across many accounts or API keys.
- Free-tier and trial abuseFree or trial API tiers frequently carry looser rate limits than paid tiers, making them an attractive low-cost entry point for initial extraction reconnaissance.
- Fine-tuned model exposureA fine-tuned model built on top of a widely available base model can still carry significant extractable value in its fine-tuning-specific behavior, even though the base weights themselves are public.
- Confidence score leakageReturning detailed probability distributions or confidence scores alongside primary outputs gives an attacker significantly richer training signal for a shadow model than a bare top-1 output would.
- Vendor and partner API accessThird parties with legitimate elevated API access are rarely subject to the same extraction-pattern monitoring applied to public-facing consumer traffic.
- Watermark survivability testingFew organizations actually test whether their chosen watermarking approach survives the specific extraction and fine-tuning techniques most likely to be used against their model.
Glossary
- Model extraction
- An attack that reconstructs a functional copy of a proprietary machine learning model using only its input-output behavior, without access to its weights or training infrastructure.
- Distillation attack
- A model extraction technique that uses a target model’s outputs as training labels for a smaller student model, efficiently capturing specialized logic and domain behavior.
- Shadow model
- A replica model trained on captured input-output pairs from a target model’s API, intended to mimic the target’s behavior at a fraction of its original training cost.
- Output perturbation
- A defense technique that introduces controlled noise into model outputs, particularly confidence scores, to degrade the training quality of any shadow model built from those outputs.
- Model watermarking
- A technique that implants a detectable, triggerable pattern into a model’s behavior so an owner can later prove ownership if a stolen or distilled copy surfaces elsewhere.
Key Takeaways
- Model extraction reconstructs a functional copy of a proprietary model purely from its input-output behavior, requiring no access to weights or infrastructure.
- The foundational research dates to 2016, but the threat has matured into a serious commercial risk for API-served large language models with high training costs.
- Rate limiting alone is insufficient because coordinated extraction campaigns distribute queries across many accounts to stay under per-account thresholds.
- Distillation attacks can efficiently capture specialized domain logic even under basic rate limits, since attackers only need to query the relevant behavior subset.
- Effective defense layers risk-weighted rate limiting, extraction-pattern query monitoring, output perturbation, and watermarking rather than relying on any single control.
- Watermarking supports ownership claims after theft is discovered but does not by itself prevent extraction from occurring.
- Enterprise governance must extend beyond the API to identity controls, vendor access, and insider-threat considerations, since a determined attacker can bypass API-level defenses through other channels.
FAQs
What is model extraction and how does it actually work?
Model extraction is an attack in which an adversary systematically queries a target model’s public API and uses the resulting input-output pairs to train a separate shadow model that replicates much of the original’s behavior, requiring no direct access to the original model’s weights or training infrastructure.
Is model extraction a new threat or has it been studied for a while?
The foundational research dates to a 2016 paper by Florian Tramer and colleagues presented at the USENIX Security Symposium, which demonstrated that model decision boundaries could be extracted with surprisingly few queries. The threat has since matured into a serious commercial risk as large language models served through APIs have become central business assets.
Why isn’t rate limiting enough to stop model extraction?
Rate limiting restricts query volume per account, but coordinated extraction campaigns distribute queries across many accounts or API keys specifically to stay under any single per-account threshold, effectively parallelizing the attack across enough identities that no individual account triggers an alert.
What is a distillation attack and why is it harder to stop than broad extraction?
A distillation attack uses a target model’s outputs as training labels for a smaller student model, efficiently capturing specialized domain logic without needing to query the model’s full capability space. Because it targets a narrower behavior subset, it can succeed even under rate limits calibrated for broader extraction attempts.
Does model watermarking actually prevent theft?
No. Watermarking implants a detectable pattern into a model’s behavior that can support an ownership claim if a stolen or distilled copy later surfaces, but it does not prevent the extraction from occurring in the first place. It works best as one layer within a broader defense program.
Can a fine-tuned model built on a public base model still be stolen?
Yes. Even though the underlying base model weights may be publicly available, the fine-tuning-specific behavior, the domain expertise and specialized logic added during fine-tuning, can still carry significant extractable value and remains a legitimate target for distillation-style extraction attacks.
What signals distinguish an extraction campaign from normal API usage?
Extraction campaigns often show systematic coverage patterns, such as queries methodically sweeping edge cases or rare regions of the input space, unusually high query diversity relative to typical application traffic, and distribution patterns inconsistent with genuine end-user behavior, all detectable through query-pattern monitoring rather than volume alone.
Should confidence scores and probability outputs be returned to API consumers?
Returning detailed confidence scores or probability distributions gives an attacker significantly richer training signal for a shadow model than a bare top-1 output would, so organizations with high extraction risk should weigh the value of exposing that granularity against the additional training signal it hands to a potential attacker.
References
- Tramer et al., “Stealing Machine Learning Models via Prediction APIs,” USENIX Security Symposium
- Praetorian, “Stealing AI Models Through the API: A Practical Model Extraction Attack”
- Blockchain Council, “Model Theft and Extraction in 2026: Risks and Defense”
- NextLabs, “AI Model Theft: Risks and Prevention”
- AquilaX, “LLM Model Extraction and Stealing Attacks: Protecting Your AI Investment”
- AI Safety Directory, “Model Theft and Extraction Attacks: Protecting AI Models (2026)”
- arXiv, “A Systematic Survey of Model Extraction Attacks and Defenses: State-of-the-Art and Perspectives”
- IEEE Transactions on Information Forensics and Security, “ModelShield: Adaptive and Robust Watermark Against Model Extraction Attack”
For related coverage, see our pieces on securing the LLM application stack, data poisoning attacks on training pipelines, which examines a related but distinct threat to model integrity, and AI vs AI defensive tooling. Together, this cluster of pieces gives security and engineering leaders a fuller picture of how training-time and inference-time threats to proprietary AI systems connect, from the data feeding a model through to the API surface exposing it to the world, and the identity layer governing who and what is allowed to query it in the first place.