| Myth | Reality |
|---|---|
| If you buy a strong enough model, messy data will not matter much. | Model quality cannot compensate for inconsistent, mislabeled, or inaccessible data; it amplifies existing data problems at scale. |
| Data readiness is primarily an IT or data-engineering problem. | Readiness spans governance, business process ownership, legal, and security teams as much as engineering. |
| A one-time data cleanup project makes data “AI-ready” for good. | Readiness is an ongoing operating discipline; data drifts, schemas change, and new sources appear continuously. |
| Real-time data pipelines are a nice-to-have for most AI use cases. | Many high-value use cases (fraud detection, dynamic pricing, support triage) fail without near-real-time data availability. |
Why Data Readiness Has Become the Real AI Bottleneck
Enterprise leaders spent the last three years debating which large language model to standardize on, which cloud to run inference in, and which vendor offered the best agent framework. Those decisions matter, but a growing body of survey data suggests they were never the binding constraint. The binding constraint is data: whether it is accurate, accessible, governed, labeled, and current enough for an AI system to reason over it reliably.
A widely cited 2026 report from Cloudera and Harvard Business Review Analytic Services found that only 7% of enterprises describe their data as completely ready for AI, while more than a quarter say their data is not very or not at all ready. That is not a rounding error — it is a structural gap between how fast organizations want to deploy AI and how prepared their underlying information systems actually are. Gartner has projected that through 2026, organizations will abandon 60% of AI projects that lack AI-ready data foundations, a figure that should reframe how leadership teams sequence AI investment: fix the foundation before scaling the use case.
This piece lays out a practical framework for assessing and improving data readiness — covering data quality, access and governance, labeling maturity, and real-time availability — along with the statistics that explain why so many AI initiatives are quietly derailed before a model ever gets evaluated.
What “AI-Ready” Data Actually Means
“AI-ready” is often used loosely, but it maps to a fairly specific set of properties. Data that is ready for traditional analytics or reporting is not automatically ready for AI, because AI systems — especially generative and agentic ones — are far less forgiving of ambiguity, missing context, and inconsistent structure than a human analyst reading a dashboard.
Practitioners generally describe data readiness across five progressive levels: raw, cleaned, labeled, feature-engineered, and fully AI-ready. Most enterprise data sits somewhere between raw and cleaned. Very little of it reaches the labeled or feature-engineered stages without deliberate investment, and even less is continuously maintained at the fully AI-ready level where it can support production inference at scale.
Four dimensions matter most when you assess where your organization actually stands:
- Data quality — accuracy, completeness, consistency, and freshness of the underlying records.
- Access and governance — who can use which data, under what policy, with what lineage and audit trail.
- Labeling and annotation maturity — how much of your data has the structured context an AI model needs to interpret it correctly.
- Real-time availability — whether data reaches the AI system fast enough for the use case it supports.
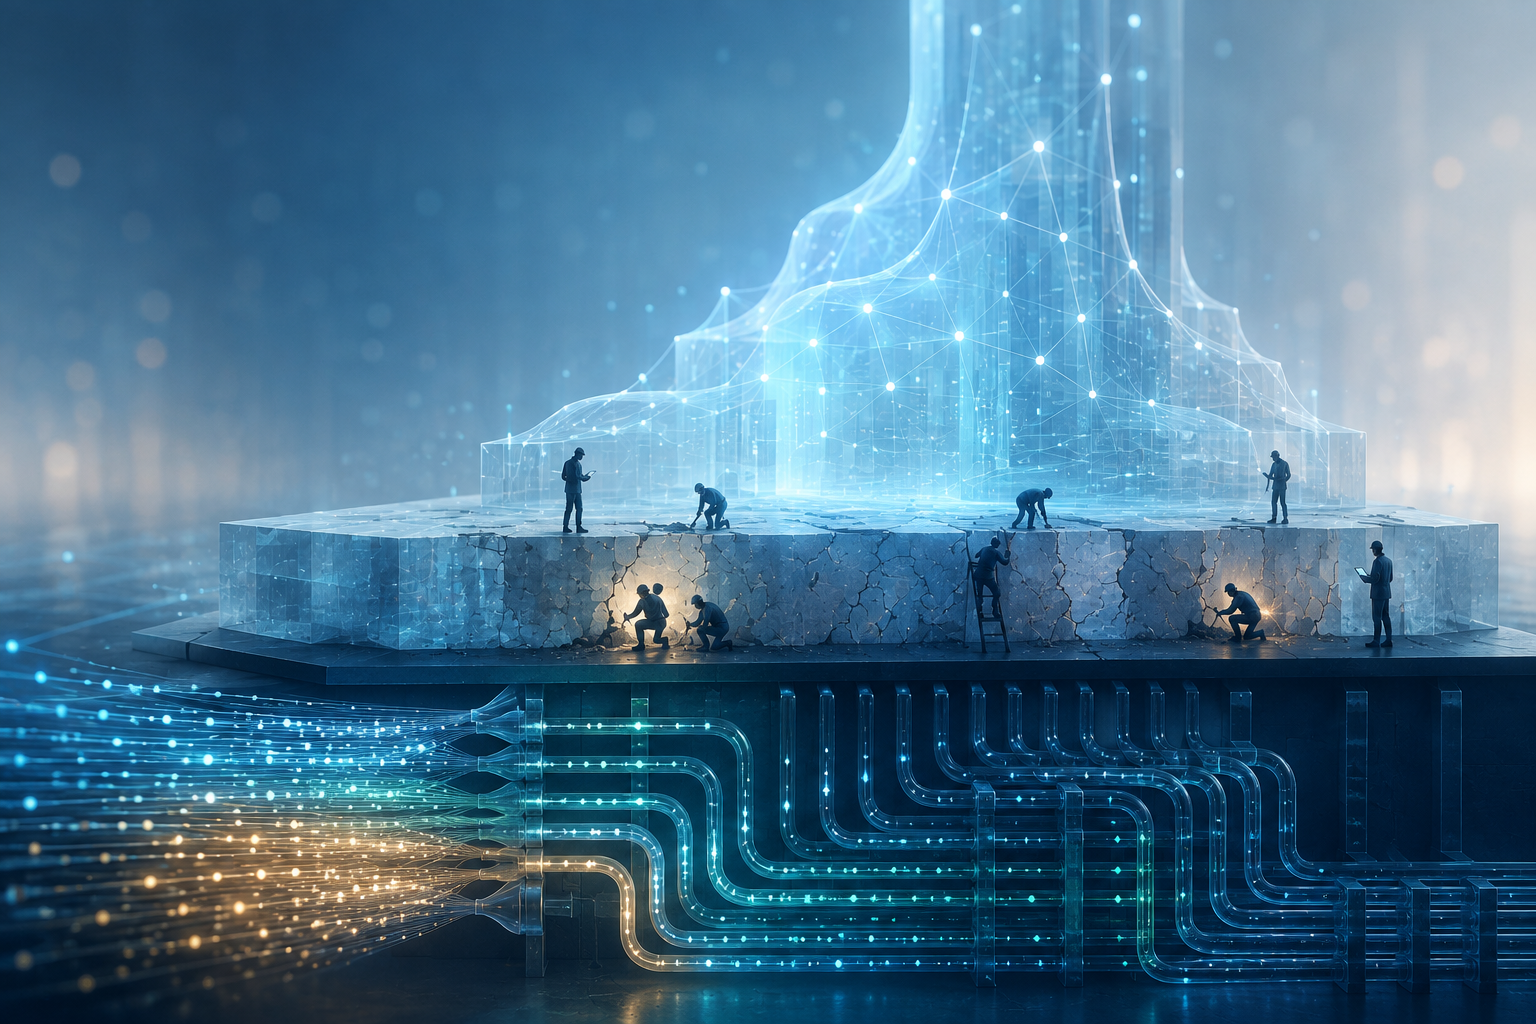
Figure: The AI Data Readiness Funnel
Picture four stacked filters between raw enterprise data sources and a production AI system: a quality filter, a governance filter, a labeling filter, and a freshness filter. In most organizations, less than a third of raw data clears all four filters on the first pass — the rest either gets rejected, gets manually patched at high cost, or silently reaches the model in a degraded state, which is where most AI accuracy complaints actually originate.
The Statistics Behind the Readiness Gap
The numbers coming out of 2026 surveys are consistent across multiple independent research efforts, which is itself notable — this is not one vendor’s marketing claim, it is a pattern.
| Finding | Figure | Source |
|---|---|---|
| Enterprises reporting data completely ready for AI | 7% | Cloudera / Harvard Business Review Analytic Services, 2026 |
| Enterprises reporting data as not very or not at all ready | 27% | Cloudera / HBR Analytic Services, 2026 |
| Respondents saying their organization should prioritize AI data quality more than it currently does | 73% | Cloudera / HBR Analytic Services, 2026 |
| Organizations with advanced data strategy capability | ~31% | Industry data maturity benchmarks, 2026 |
| AI projects Gartner projects will be abandoned through 2026 due to lack of AI-ready data | 60% | Gartner, cited across multiple 2026 industry reports |
| Organizations with established analytics capability that also show mature adoption and education | 19% of 77% | 2026 enterprise data readiness benchmarking |
Read together, these figures describe an industry that has built reporting and analytics infrastructure over the last decade but has not extended that infrastructure into the governance, labeling, and freshness disciplines that AI specifically requires. The gap between having data and having AI-ready data is where most pilot projects quietly die — a pattern explored in more depth in our companion piece on why most AI pilots never reach production.
A Practical Framework for Assessing Readiness
Rather than treating data readiness as an abstract governance exercise, enterprises that succeed treat it as a scoring exercise against four pillars, each assessed per use case rather than as a single organization-wide grade.
1. Data Quality
Quality assessment should answer: how complete are the records, how consistent are formats and definitions across source systems, and how often does the data actually match ground truth? Many organizations discover during an AI project kickoff that the same customer entity is represented three different ways across CRM, billing, and support systems — a problem that was invisible in legacy BI dashboards but becomes a direct source of hallucination and error when an AI agent tries to reason across those systems.
2. Access and Governance
Governance maturity determines whether the right data can legally and technically reach an AI system at all. This includes role-based access control, data lineage tracking, retention policy enforcement, and — increasingly — explicit AI-use permissions layered on top of existing access controls, since many datasets were never contractually cleared for use in model training or inference. Organizations building a formal governance function around this often anchor it inside a dedicated group; see our piece on building an AI center of excellence for how that function typically gets structured.
3. Labeling and Annotation Maturity
Labeling maturity is the most underestimated readiness dimension. Structured labels, metadata tags, and taxonomy consistency are what let a model distinguish a “returned” order from a “cancelled” one, or a “resolved” support ticket from one that was simply closed without resolution. Enterprises with mature labeling pipelines typically maintain a centralized taxonomy team and continuous annotation review cycles rather than one-off tagging projects.
4. Real-Time Availability
Not every AI use case needs millisecond-fresh data, but a large share of the highest-ROI use cases do: fraud detection, dynamic pricing, real-time support triage, and inventory-aware recommendations all degrade sharply if the underlying data lags by hours rather than seconds. Assessing readiness means mapping each candidate use case against the actual latency of its supporting data pipeline, not the latency the pipeline was designed for five years ago under different requirements.
| Readiness Dimension | Common Failure Pattern | What Good Looks Like |
|---|---|---|
| Data quality | Duplicate and conflicting records across systems of record | Single source of truth with automated reconciliation and quality scoring |
| Governance | Access requests resolved ad hoc, no lineage tracking | Role-based access with automated lineage and AI-use consent tracking |
| Labeling | Inconsistent tags applied manually by different teams | Centralized taxonomy with continuous annotation quality review |
| Real-time availability | Batch pipelines refreshing every 24 hours for time-sensitive use cases | Streaming or near-real-time pipelines matched to use-case latency needs |
Building the Assessment Into Your AI Roadmap
Data readiness assessment should happen before use case selection is finalized, not after a pilot has already been scoped. Leading organizations run a lightweight readiness scorecard against each candidate use case, scoring quality, governance, labeling, and freshness on a simple scale, and use the aggregate score to sequence which use cases go first. This sequencing decision connects directly to broader AI maturity planning — organizations that map readiness against a maturity model tend to make more defensible prioritization calls; see our comparison of AI maturity models and how to use them.
The organizations that get this right also tend to invest early in the platform team responsible for maintaining data pipelines at production quality, rather than treating data engineering as a one-time project cost. Our guide on building an ML platform team covers how that function is typically staffed and funded.
Common mistake
Treating a single point-in-time data quality audit as sufficient proof of readiness. Data quality decays continuously as new sources are added, schemas change, and business processes evolve — a scorecard from six months ago tells you almost nothing about whether a pipeline is production-safe today. Readiness needs a standing measurement cadence, not a one-time certificate.
What worked
Several enterprises that successfully scaled AI beyond pilot stage report the same pattern: they picked a narrow, well-governed data domain first (often customer support or a single product line), proved the readiness framework worked end to end, and only then expanded scope. Trying to fix data readiness organization-wide before any AI use case ships tends to stall in governance committees indefinitely.
Frequently Overlooked Readiness Factors
- Schema driftSource systems change field structures without notifying downstream AI pipelines, silently breaking assumptions the model was trained on.
- Shadow data storesSpreadsheets and departmental databases outside official governance that quietly feed into AI workflows through manual exports.
- Consent and licensing gapsData collected for one purpose (support tickets, for example) may not be contractually cleared for AI training or inference use.
- Annotation inconsistency across teamsDifferent departments applying different tagging conventions to the same category of data, fragmenting the taxonomy an AI system relies on.
- Latency mismatch by use caseAssuming a data pipeline built for daily reporting is fast enough for a real-time AI use case without re-verifying against the new requirement.
- Ownership ambiguityNo single accountable owner for a dataset’s quality once it crosses departmental boundaries, so quality issues get discovered only after model failures.
Governance as a Continuous Operating Discipline
The organizations furthest ahead on data readiness treat governance as an operating discipline with named owners, recurring review cadences, and measurable service levels — not as a compliance checkbox completed once before a project launches. This typically means a data quality service level agreement per critical dataset, an escalation path when quality drops below threshold, and a standing forum where data owners, AI product teams, and legal or compliance stakeholders review readiness gaps together on a monthly or quarterly basis.
This operating model also needs to survive organizational change. As AI initiatives move from pilot to scaled production, the teams responsible for data pipelines often need to be restructured or expanded — a topic covered in our piece on restructuring teams around AI.
Glossary
- Data readiness level
- A staged classification of how prepared a dataset is for AI use, typically ranging from raw through cleaned, labeled, feature-engineered, to fully AI-ready.
- Data lineage
- The documented trail showing where a piece of data originated, how it was transformed, and where it has been used, including in AI training or inference.
- Schema drift
- Unplanned changes to the structure of a data source over time that can silently break downstream systems relying on the original structure.
- Annotation taxonomy
- A standardized set of labels and categories applied consistently across a dataset so an AI system can interpret it correctly.
- Real-time data pipeline
- An infrastructure pattern that delivers data to a consuming system within seconds of its creation, as opposed to batch pipelines that refresh on a schedule.
Key Takeaways
- Only about 7% of enterprises describe their data as completely AI-ready, according to 2026 survey data from Cloudera and Harvard Business Review Analytic Services.
- Gartner projects that through 2026, organizations will abandon 60% of AI projects that lack AI-ready data foundations.
- Data readiness spans four pillars: data quality, access and governance, labeling and annotation maturity, and real-time availability.
- Readiness must be assessed per use case, not as a single organization-wide score, since latency and quality needs vary sharply across use cases.
- Governance works best as a continuous operating discipline with named owners and recurring review cadences, not a one-time audit.
- Narrow, well-governed pilot domains that prove the readiness framework end to end tend to scale more successfully than organization-wide readiness overhauls.
- Data readiness assessment should happen before use case selection is finalized, feeding directly into how initiatives are sequenced on the AI roadmap.
FAQs
What does “AI-ready data” actually mean?
AI-ready data is data that is accurate, consistently structured, properly governed with clear access permissions, sufficiently labeled with taxonomy context, and available fast enough to meet the specific use case’s latency needs. It goes beyond the quality bar needed for traditional reporting or analytics dashboards.
How common is the data readiness problem in enterprises?
Very common. A 2026 Cloudera and Harvard Business Review Analytic Services report found only 7% of enterprises consider their data completely ready for AI, while over a quarter describe their data as not very or not at all ready, despite widespread AI adoption efforts already underway.
Why do AI projects fail even when the model performs well in testing?
Models are frequently tested on curated, cleaned datasets that do not reflect the messy, inconsistent production data the system encounters after deployment. Gartner projects 60% of AI projects will be abandoned through 2026 specifically due to lack of AI-ready data foundations, not model limitations.
What are the four pillars of a data readiness assessment?
The four pillars are data quality (accuracy and consistency), governance (access control and lineage), labeling maturity (structured annotation and taxonomy), and real-time availability (whether data reaches the AI system fast enough for the use case). Each should be scored separately per candidate use case.
Should data readiness be assessed once or continuously?
Continuously. Data quality decays as new sources appear, schemas change, and business processes evolve, so a point-in-time audit quickly becomes stale. Leading organizations maintain standing review cadences and service level agreements for critical datasets rather than treating readiness as a one-time certification.
Which AI use cases are most sensitive to data freshness?
Use cases like fraud detection, dynamic pricing, real-time support triage, and inventory-aware recommendations depend heavily on near-real-time data. Batch pipelines refreshing once a day are often insufficient for these use cases even if they work fine for traditional reporting.
Who should own data readiness inside an enterprise?
Ownership should be shared across data engineering, governance and compliance, and the business teams that generate the data, with a named accountable owner per critical dataset. Many organizations formalize this through a dedicated AI center of excellence that coordinates readiness across departments.
How should data readiness influence AI use case prioritization?
Readiness scores should feed directly into use case sequencing — organizations that score candidate use cases against quality, governance, labeling, and freshness before committing tend to prioritize the use cases most likely to succeed first, rather than the most strategically appealing but least data-ready ones.
References
- Cloudera and Harvard Business Review Analytic Services, “Only 7% of Enterprises Say Their Data Is Completely Ready for AI,” 2026 press release and report
- Gartner, AI project abandonment projections due to lack of AI-ready data foundations, as cited across multiple 2026 industry analyses
- Drexel University LeBow College of Business and Precisely, “2026 State of Data Integrity and AI Readiness” survey findings
- ZAI Institute, “The AI Readiness Gap — 2026 Enterprise Survey Findings”
- Agility at Scale, “Data Readiness Assessment for AI: Checklist, Framework, and Scoring”
- Atlan, “AI Readiness Assessment: Your 2026 Implementation Guide”
For related planning context, see our companion pieces on total cost of ownership for enterprise AI deployments and measuring AI ROI, both of which depend heavily on the data foundation described here.