| Aspect | Traditional siloed model | Personal data vault model |
|---|---|---|
| Where data lives | Copied and duplicated inside every service that touches it | Stored once in a vault the individual controls (a Pod, PDS, or equivalent) |
| Who grants access | The service itself, based on its own terms of use | The individual, via explicit, scoped, and revocable permissions |
| What happens on account deletion | Data often persists in backups, analytics tools, and partner systems | Revoking access can cut off a specific app while the underlying data stays intact elsewhere |
| Portability | Requires manual export/import between services, if supported at all | Native, since all authorized apps read from and write to the same store |
The Problem With Today’s Siloed Data Model
Every app, retailer, and platform a person uses today typically keeps its own private copy of that person’s data. A change of address gets typed into a banking app, a delivery app, a subscription service, and a dozen others, each storing an independent copy with its own retention rules, its own security posture, and its own breach risk. This is the siloed model, and it is the default architecture of the modern internet: data does not travel with the individual, it gets duplicated wherever the individual interacts.
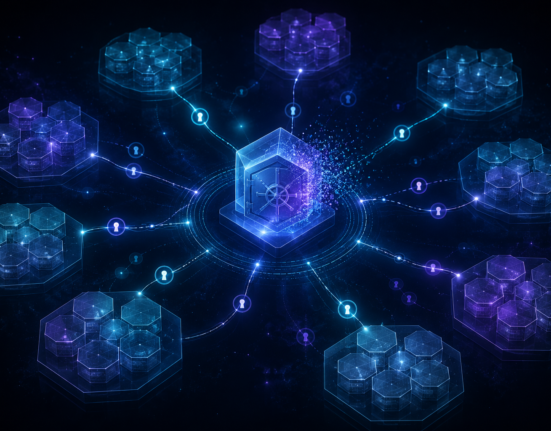
The personal data vault, sometimes called a personal data store, personal online datastore, or Pod, is a proposed alternative architecture. Instead of each service holding its own copy, the individual holds a single store of their data, and services request scoped, time-limited, revocable access to exactly the fields they need, rather than taking a full copy home with them. The best-known implementation is Solid, the specification originally developed at MIT, where individuals store personal data in “Pods,” personal online data stores that combine user control over storage location with fine-grained, revocable access control for any application that wants to read or write to them.
How the Architecture Actually Works
Pods, operators, and the MyData model
In the Solid specification, a Pod can be hosted by a Pod provider or self-hosted on infrastructure the individual controls, and it holds structured personal data that any authorized application can request access to through standardized, permissioned APIs. The Nordic-originated MyData model describes a closely related architecture using different vocabulary: the individual is the “Account Owner,” a “MyData Operator” hosts the account and manages consent, “Sources” are the systems that originally generated the data, and “Sinks” are the applications requesting access to use it. In both models, consent is meant to be dynamic and machine-readable, so individuals can grant and withdraw access to specific data categories without needing a lawyer or a support ticket.
Data trusts: a governance-first variant
A related but distinct concept is the data trust, where a trustee (which could be a nonprofit, cooperative, or fiduciary body) manages data-sharing decisions on behalf of a group of individuals under an agreed legal and governance structure, rather than each individual configuring permissions themselves one app at a time. Data trusts trade some individual granularity for collective bargaining power, useful in contexts like patient data cooperatives or gig-worker data pools where individuals have limited leverage negotiating with a platform alone.
| Model | Who controls access decisions | Best suited for |
|---|---|---|
| Solid Pods | The individual, through Pod-level permissions | Individuals or organizations wanting direct technical control over a personal data store |
| MyData operator model | The individual, mediated through a MyData operator managing consent | National or sector-level personal data ecosystems (health, HR, finance) |
| Data trust | A collective trustee acting on behalf of a group | Groups with limited individual bargaining power, such as gig workers or patients |
| Traditional siloed storage | Each individual service provider | The current default; no individual data ownership layer |
Real-World Deployments Beyond the Research Lab
Personal data vaults have moved from academic proposals to production pilots. In Belgium, the Athumi platform operates Solid-based Pods as “Personal Online Datastores,” letting individuals store personal data and choose exactly who can access which fields and for how long. Athumi and the staffing company Randstad have implemented an end-to-end HR use case in a Solid production environment, where employment data moves through a Pod rather than being re-entered and re-copied across recruiter, employer, and background-check systems. In financial services, ING has piloted Solid-based data vaults that give customers direct control over data sharing between banking products, an approach the bank has described publicly as making data sovereignty a practical reality rather than a policy statement. Recent academic work published in early 2026 on enforcing data sovereignty with Solid Pods has focused specifically on strengthening the technical guarantees behind these access grants, addressing early criticism that permission systems were easier to configure than to actually enforce end to end.
| Sector | Example deployment | Scope of the pilot |
|---|---|---|
| HR and staffing | Randstad and Athumi, Belgium | End-to-end employment verification data moved through Solid Pods in a production environment |
| Banking and financial services | ING | Customer-controlled data sharing between banking products via Solid-based vaults |
| Consumer data platforms | Athumi Personal Online Datastores | Consumer-facing Pods letting individuals choose who accesses which fields, and for how long |
| Academic and standards research | ACM-published Solid Pod sovereignty research (2026) | Strengthening the technical enforcement guarantees behind access grants, not just their configuration |
How a scoped access request flows through a personal data vault
An application asks the vault for a narrow slice of data, such as a verified age range rather than a full birthdate, the individual approves or denies the specific request through a consent interface, and if approved, the app receives only that scoped field for a defined period, with the grant fully visible and revocable from the individual’s own dashboard at any time.
What Individuals and Organizations Actually Gain
For individuals: one place to manage, not dozens
Instead of updating an address in fifteen different accounts, or trying to remember which of a hundred services holds an old copy of a document, an individual with a personal data vault updates it once, and every application with a still-valid grant sees the update immediately. Revoking an app’s access becomes an actual, dashboard-level action rather than a support request that may or may not be honored.
For organizations: less duplicated liability
Organizations that request scoped access rather than importing and storing a full copy carry a smaller breach footprint; there is simply less duplicated personal data sitting in more places waiting to be exposed. This also changes the compliance calculus for regulations built around minimization and storage limitation, since an organization that never held a full copy has a much narrower deletion and disclosure obligation to begin with.
For the broader ecosystem: portability that actually works
Because every authorized application reads from the same underlying store, switching from one service to a competing one does not require a manual export-and-reimport process; the new application simply requests access to the same vault, addressing a portability problem that current “download your data” tools solve only partially and inconsistently.
Common mistake
Assuming a personal data vault automatically means better privacy the moment it is adopted. A Pod configured with overly broad, permanent access grants, the digital equivalent of handing over a master key instead of a scoped one, recreates the same over-sharing problem the architecture was meant to solve; the privacy benefit depends entirely on how narrowly and how often the individual actually scopes each grant, not on the existence of the vault itself.
What worked
Deployments that started with a single, well-defined use case, such as the Randstad-Athumi HR pilot limited to employment verification data, before expanding scope saw far higher adoption and fewer configuration errors than attempts to migrate an individual’s entire data footprint into a vault on day one. Narrow, concrete pilots built trust in the model before asking users to manage broader, more abstract permission sets.
Barriers to Wider Adoption
The architecture faces real obstacles that go beyond technical feasibility. Network effects favor the status quo: a single dominant platform has little commercial incentive to give up its exclusive copy of user data in favor of a shared, individual-controlled store it does not fully own. Standardization is still maturing, and interoperability between different Pod providers, operators, and legacy systems that were never built with a permissioned-access model in mind remains a significant integration cost. There is also a genuine usability challenge: asking ordinary individuals to manage dozens of granular, per-application data grants risks recreating the same consent fatigue that already plagues cookie banners, unless the interface abstracts most of that complexity into sensible defaults.
Frequently Overlooked Elements of Personal Data Vault Design
- Vault provider trustThe Pod or operator hosting the vault becomes a new, highly concentrated point of trust and a valuable target, even if it never directly accesses the content.
- Consent fatigue at scaleFine-grained permission requests can overwhelm users the same way cookie banners did, unless defaults and templates reduce decision load.
- Offline and outage resilienceIf the vault or its host is unreachable, every dependent application loses access simultaneously, a new single point of failure worth planning around.
- Legacy system integrationExisting enterprise systems built around owning a full copy of user data need real re-architecture, not just an API wrapper, to consume scoped vault access properly.
- Enforcement versus configurationA permission being set correctly in the interface is not the same as it being technically enforced end to end, a gap recent Solid research has specifically targeted.
- Portability across vault standardsSolid Pods, MyData operators, and proprietary vault products are not yet fully interoperable with each other, risking a new form of vendor lock-in one layer up.
- Vulnerable users and delegated controlChildren, elderly users, and people without reliable digital access need a workable model for guardianship or delegated vault management, still an open design question.
Glossary
- Personal data vault
- A storage space controlled by an individual where their data is kept once, with applications granted scoped, revocable access rather than holding independent copies.
- Solid Pod
- The personal online data store defined by the Solid specification, hosted by a Pod provider or self-hosted, that individuals use to store and control access to their own data.
- MyData model
- A Nordic-originated framework for human-centered personal data management built around an Account Owner, a MyData Operator, Sources, and Sinks.
- Data trust
- A governance structure in which a trustee manages data-sharing decisions on behalf of a group of individuals under an agreed legal framework.
- Scoped access
- A permission grant limited to a specific data field, purpose, and time window, rather than blanket access to an individual’s entire data store.
Key Takeaways
- Personal data vaults flip the default architecture: data lives once, in a store the individual controls, instead of being copied into every service that touches it.
- Solid Pods, the MyData operator model, and data trusts are three distinct implementations of the same underlying idea, with different tradeoffs in control and governance.
- Real production deployments already exist, including HR and banking pilots in Europe, moving the concept beyond academic proposals.
- Scoped, revocable access grants are the core mechanism; without narrow scoping, a vault can recreate the same over-sharing risk it was meant to solve.
- Organizations benefit from a smaller breach footprint by requesting scoped access instead of importing and storing full copies of personal data.
- Adoption faces real barriers: network effects favor incumbent platforms, and consent fatigue is a genuine usability risk at scale.
- Enforcement of access permissions, not just their configuration, is an active area of technical research and a key gap still being closed.
FAQs
What is a personal data vault?
A personal data vault is a storage space controlled by an individual, where their personal data is kept in one place and applications request scoped, revocable access to specific fields rather than each service holding its own independent copy of the data.
How is a Solid Pod different from cloud storage like Dropbox?
Cloud storage holds files an individual chooses to upload, but does not standardize how outside applications request permissioned access to structured personal data. A Solid Pod is built around a specification for exactly that: standardized, revocable, application-level access grants to data an individual controls.
Is the MyData model the same thing as a Solid Pod?
They are related but not identical. MyData is a broader governance and consent framework describing roles like the Account Owner and MyData Operator, while Solid is a specific technical protocol for Pods. A MyData-based ecosystem could, in principle, be implemented using Solid Pods as the underlying storage technology.
What is a data trust and how does it differ from a personal data vault?
A data trust uses a trustee to make data-sharing decisions on behalf of a group of individuals under a shared legal and governance structure, trading some individual granularity for collective bargaining power, whereas a personal data vault gives each individual direct, personal control over their own access grants.
Are personal data vaults actually being used today, or is this still theoretical?
They are in active production use in several pilots, including a Solid-based HR data-sharing use case between Randstad and Athumi in Belgium, and banking-sector pilots exploring customer-controlled data sharing between financial products.
Do personal data vaults eliminate the need for privacy regulation like GDPR?
No. They provide a technical architecture that can make compliance easier, particularly around data minimization and access control, but legal obligations around consent, security, and lawful processing still apply to any organization or operator handling the underlying data.
What happens if the company hosting a Pod or vault goes out of business?
This is a genuine open risk in current implementations; individuals typically need the ability to export or migrate their vault to a different provider or self-hosted instance, which is why interoperability between Pod providers is an active area of standardization work.
Why haven’t personal data vaults replaced the traditional siloed model already?
Adoption is slowed by network effects that favor platforms already holding exclusive data copies, immature interoperability standards between vault providers, integration costs for legacy systems, and the usability risk of asking users to manage many granular permission grants without triggering consent fatigue.
Personal data vaults sit alongside other tools individuals and organizations use to rebalance data control: readers comparing techniques for keeping vault-adjacent data usable without full identification should see anonymisation vs pseudonymisation, while organizations building consent flows for scoped access grants may find consent management in a cookieless web directly relevant. Multinational deployments of vault infrastructure should also review data sovereignty requirements by region and the mechanics of cross-border data transfer after Schrems, and teams evaluating where to host a self-hosted Pod can compare sovereign cloud options. Organizations designing retention rules for data flowing through a vault should also read data retention policy design and automated deletion.
- ACM Digital Library, “Enforcing Data Sovereignty with Solid Pods” (2026)
- Philip Smet, ING Blog (Medium), “Controlling Your (Personal) Data With a Solid-Based Data Vault Is Reality”
- Athumi, “The Athumi Pod: Access to Your Customers’ Premium Data”
- Athumi, “Solid: Vault Technology for Consumers and Businesses”
- MyData.org, “MyData: A Nordic Model for Human-Centered Personal Data Management and Processing”
- HIIT, “MyData Architecture: Consent-Based Approach for Personal Data Management”
- PMC / National Institutes of Health, “Personal Data Stores (PDS): A Review”